AI Reproducibility: Reconstruct What an Avatar Actually Ran
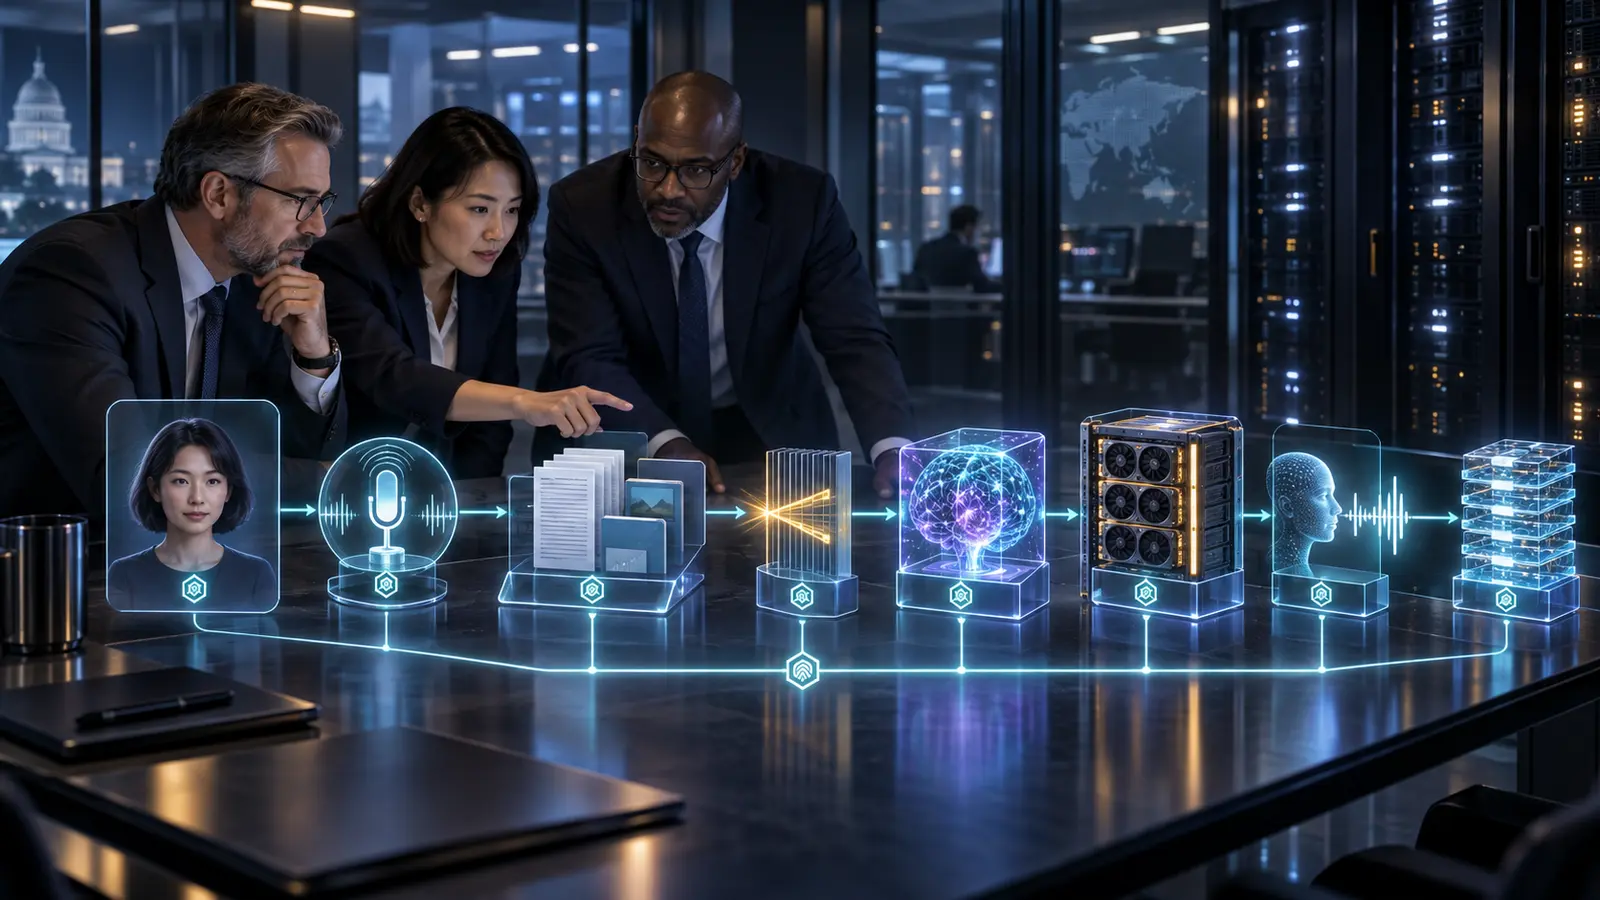
AI reproducibility for a real-time avatar should mean that an authorised team can reconstruct what system ran, what governed it and what evidence it used—not that the model must repeat the same sentence word for word. For banks, governments and regulated enterprises, the useful target is a verifiable runtime fingerprint linked to a controlled release, a governed evidence path and defined behavioural tolerances.
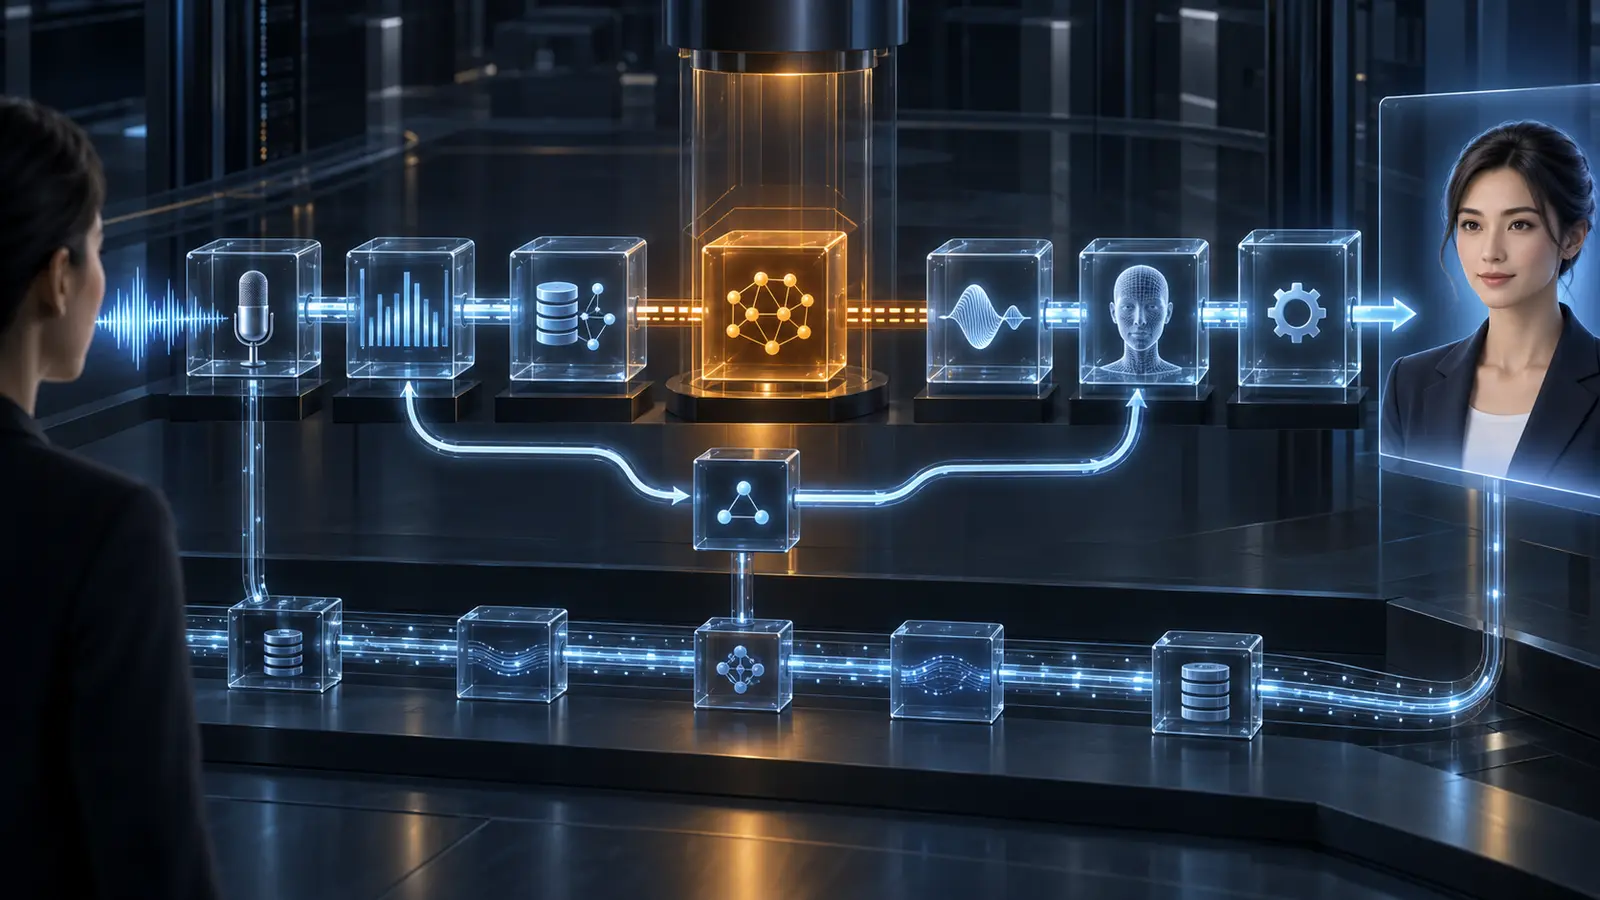
This distinction matters because an avatar is a live system of systems. Speech recognition, retrieval, language generation, safety policy, tools, voice synthesis, rendering, media delivery and external records may all influence one turn. Replaying only the prompt against a model with the same marketing name proves very little.
This guide defines four levels of reproducibility, an eight-part runtime fingerprint, five reconstruction modes and twelve production tests. It extends Yepic’s AI bill of materials for avatar dependencies: the bill identifies what belongs to an approved release; the runtime fingerprint proves which combination handled a particular session.
Do not confuse reproducibility with identical output
“Reproduce the result” can describe four different promises. A procurement or assurance document should state which one is required.
1. Artefact reproducibility
The team can obtain and verify the exact model weights or service version, adapters, tokeniser, prompts, policies, voice and avatar assets, containers, libraries and configuration used. Immutable identifiers and cryptographic digests are stronger evidence than labels such as “production”, “latest” or a mutable model alias.
2. Execution reproducibility
The team can rebuild or re-enter a materially equivalent environment: operating system, GPU class, driver, inference engine, numerical precision, decoding settings, feature flags and service topology. This does not automatically produce bit-for-bit identical output.
PyTorch’s current reproducibility guidance, for example, says complete reproducibility is not guaranteed across releases or platforms, or even between CPU and GPU with identical seeds. Deterministic operations can also reduce performance. That is a framework-specific example, not a requirement to use PyTorch; it illustrates why a seed and model name are not a complete enterprise control.
3. Evidence-path reproducibility
A reviewer can reconstruct which authenticated context, knowledge revisions, access-control decisions, policy gates, tool proposals and external responses shaped the observable result. This is often more valuable than identical wording. If an avatar gave an incorrect account answer, the bank needs to know whether the cause was stale retrieval, a permissions failure, an unsafe model inference or a changed downstream record.
4. Behavioural reproducibility
Repeated or equivalent tests remain within approved tolerances: the answer is supported by permitted sources, prohibited data is not disclosed, the correct action boundary holds, language and voice meet quality thresholds, and latency stays inside its operating range. Wording and animation may vary while the control outcome remains acceptable.
Define the required level per use case. A low-risk public-information concierge may need release traceability and behavioural regression tests. An authenticated service that prepares a regulated transaction may also require protected reconstruction of the precise evidence and authorisation path.
Create an eight-part runtime fingerprint
Generate a compact, machine-readable fingerprint at session start and update it when a material component changes. It should reference governed records rather than copy every sensitive input into one log.
1. Session and purpose envelope
Record a unique trace identifier, time source, channel, deployment zone, declared purpose, language route and relevant policy profile. Use a pseudonymous subject reference unless direct identity is required for the investigation. State which clock is authoritative so events from browser, media, model and business systems can be ordered reliably.
2. Approved release identity
Bind the session to the exact release bundle and environment overlay. Include the approval reference and effective runtime state—not merely the configuration repository’s intended state. Yepic’s guide to controlling AI configuration drift explains why a deployed process may silently load a different prompt, model profile or endpoint from the one reviewers approved.
3. Model and inference identity
Identify each active speech, language, moderation, translation, voice and rendering model. Capture an immutable version or digest where available, base model and adapter relationships, tokeniser, inference engine, precision, decoding method, sampling parameters and random seed where meaningful. Record routing and fallback choices at the point they occur.
4. Knowledge and retrieval snapshot
Record the source collection and revision, embedding model, index build, chunking and ranking configuration, freshness boundary, permission-filter version and identifiers for the passages returned. An index can change while the language model remains fixed. A later replay against today’s knowledge is therefore a new experiment, not a reconstruction of yesterday’s answer.
5. Policy and decision controls
Capture the versions of system instructions, disclosure rules, guardrails, confidence thresholds, escalation logic, redaction rules and action policy. Record the observable decision from each relevant gate: allowed, blocked, transformed, restricted or handed over. Do not retain hidden chain-of-thought; it is neither necessary nor a reliable audit record.
6. Tool and external-state references
Identify tool schemas, API versions, permission scopes and idempotency keys. Preserve request and response receipts appropriate to the data class. External state is time-dependent: an account balance, flight status or citizen record retrieved later may legitimately differ. Where the source system supports it, reference its transaction or snapshot version.
7. Runtime, GPU and media environment
Include container digests, relevant libraries, operating system, accelerator and driver, inference profile, codec, media server, browser or kiosk build and network route. Record only details that can materially affect behaviour, security or performance. A complete hardware inventory that nobody can use is less valuable than a controlled compatibility record.
8. Observable output and outcome
Link the approved text, captions, speech and action receipts to their generating turn. For higher-consequence workflows, distinguish what the model proposed, what policy permitted, what the avatar presented and what a downstream system actually executed. Store raw audio, video or transcripts only where a defined purpose and retention policy justify them.
Protect evidence without keeping every conversation
Reproducibility is not permission to build a permanent surveillance archive. Start with the claims an investigator may need to prove, then retain the minimum evidence for those claims. Yepic’s privacy-minimised AI audit-trail design shows how structured identities, versions, decisions and receipts can provide stronger evidence than indiscriminate recordings.
Use references, version identifiers and protected content stores with separate access controls. A plain hash of predictable personal information can sometimes be guessed; where a digest is used to correlate sensitive values, consider a keyed construction, strict key access and a documented retention period. Encryption, access logging, legal hold and deletion need to follow the data classification of the underlying content.
Integrity matters too. Sign or otherwise protect release records and critical events from silent alteration. Sequence events and link them to a trusted time source. Record gaps explicitly: “transcript not retained by policy” is more honest than an apparently complete reconstruction assembled from partial logs.
Use five reconstruction modes
Not every investigation needs the original customer content. Define escalating modes before an incident.
- Manifest reconstruction: verify that the approved artefacts, configuration and runtime environment can still be assembled.
- Synthetic replay: run a controlled test conversation with the recorded release and representative, non-sensitive inputs.
- Evidence-path reconstruction: rebuild the sequence of retrieval, policy, authorisation and external-action events from references and receipts.
- Protected replay: under exceptional authorised access, replay retained content inside an isolated investigation environment.
- Counterfactual comparison: run the same governed test against the current and historical releases to determine which change affects the outcome.
A replay environment should not invoke live customer actions. Replace payment, case-management, booking or messaging tools with captured responses or test doubles. Mark every reconstructed output as a test artefact so it cannot be mistaken for a real communication or transaction.
Compare the result at the right level. For generated language, use source support, policy outcome, semantic task completion and prohibited-behaviour tests—not only exact-string matching. For captions, pronunciation, latency and animation, define measurable tolerances. For business actions, require exact agreement on typed parameters, approval and downstream receipt.
Connect the registry, lineage and audit records
A model registry is useful but insufficient. The current MLflow Model Registry documentation illustrates how a registry can connect versions to experiments, runs, parameters and deployment status. An avatar also needs lineage across knowledge, policies, identity assets, tools, media and runtime dependencies.
OpenLineage provides an open pattern for recording metadata about jobs, runs and datasets, while the W3C PROV-O recommendation provides general concepts for entities, activities, agents and derivation. These are implementation references, not mandatory Yepic components. The architectural requirement is a consistent relationship graph that can answer: which approved entities were used by this activity, who authorised them and what outcome was generated?
NIST’s current AI RMF Measure playbook recommends documenting development, testing, configuration, provenance and auditability. The NCSC’s model and dataset lifecycle guidance similarly calls for version-controlled, reviewable assets and standardised machine-readable metadata. Neither source promises that the same generative output will recur.
Choose the evidence boundary by deployment model
Customer-hosted deployment can give the organisation direct access to model artefacts, GPU runtimes, local knowledge snapshots and event stores. It also gives the customer more responsibility for registry operation, time synchronisation, key management, storage integrity and reconstruction drills. On-premise hosting does not create reproducibility automatically.
Managed cloud can provide consistent release automation, managed registries and provider-operated telemetry. The customer may receive a service version and event references rather than internal model digests or infrastructure detail. Procurement should define which evidence the provider will supply, how long versions remain reconstructable and how provider-side changes are communicated.
Private or sovereign cloud can place content and evidence in a controlled region or tenant while retaining managed infrastructure. Visibility and control depend on the responsibility split, not the label. A hybrid design may keep protected content and action receipts with the customer while sharing only health metrics or release identifiers with support teams.
Yepic can scope cloud, private-cloud, sovereign and customer-hosted avatar architectures, including deployments on customer-controlled GPUs where appropriate. The fingerprint depth, retention and replay capability must be designed for the chosen components, licences and operating model.
Run twelve production tests
- A session can be tied to one approved release and effective environment overlay.
- Every model, adapter, tokeniser, prompt, policy and knowledge index has an immutable identifier.
- A mid-session fallback or routing change creates a new fingerprint event.
- The team can identify the exact source revisions and permission decision behind a grounded answer.
- Tool proposals, approvals and downstream outcomes remain distinguishable.
- GPU, driver, inference profile and precision differences are visible when material.
- Clock skew cannot silently reorder security or business events.
- A synthetic replay cannot call live customer systems.
- Behavioural comparisons use defined tolerances rather than exact wording alone.
- An authorised protected replay can be performed without copying evidence to an uncontrolled environment.
- The reconstruction record states what was not retained and why.
- A timed drill can reconstruct one selected session and explain every unresolved gap.
Test reconstruction before procurement closes
Yepic’s Abu Dhabi Aviation and Oracle enterprise avatar integration involved separate development and production environments, API and iframe integration, real-time streaming, captions, microphone behaviour, WebRTC and network testing, browser remediation, cybersecurity support and ongoing maintenance. Those layers show why “which model?” is only one part of reconstructing an enterprise avatar.
The case study is not presented as a completed customer-hosted reproducibility implementation. Yepic’s proprietary real-time avatar technology and private deployment capability still require a properly scoped design around the customer’s selected speech, language, knowledge, voice, GPU and operating components.
Before launch, select one representative session and give an independent reviewer its trace identifier. Ask them to name the exact release, rebuild the material runtime environment, identify the evidence and policy path, confirm any external action and run a safe behavioural replay. Record the time, missing artefacts, privileged access required and questions that remain unanswered. If the team can only replay a prompt and hope for the same words, it has repetition—not reproducibility.