Context Engineering for AI Agents: Build the Turn Packet
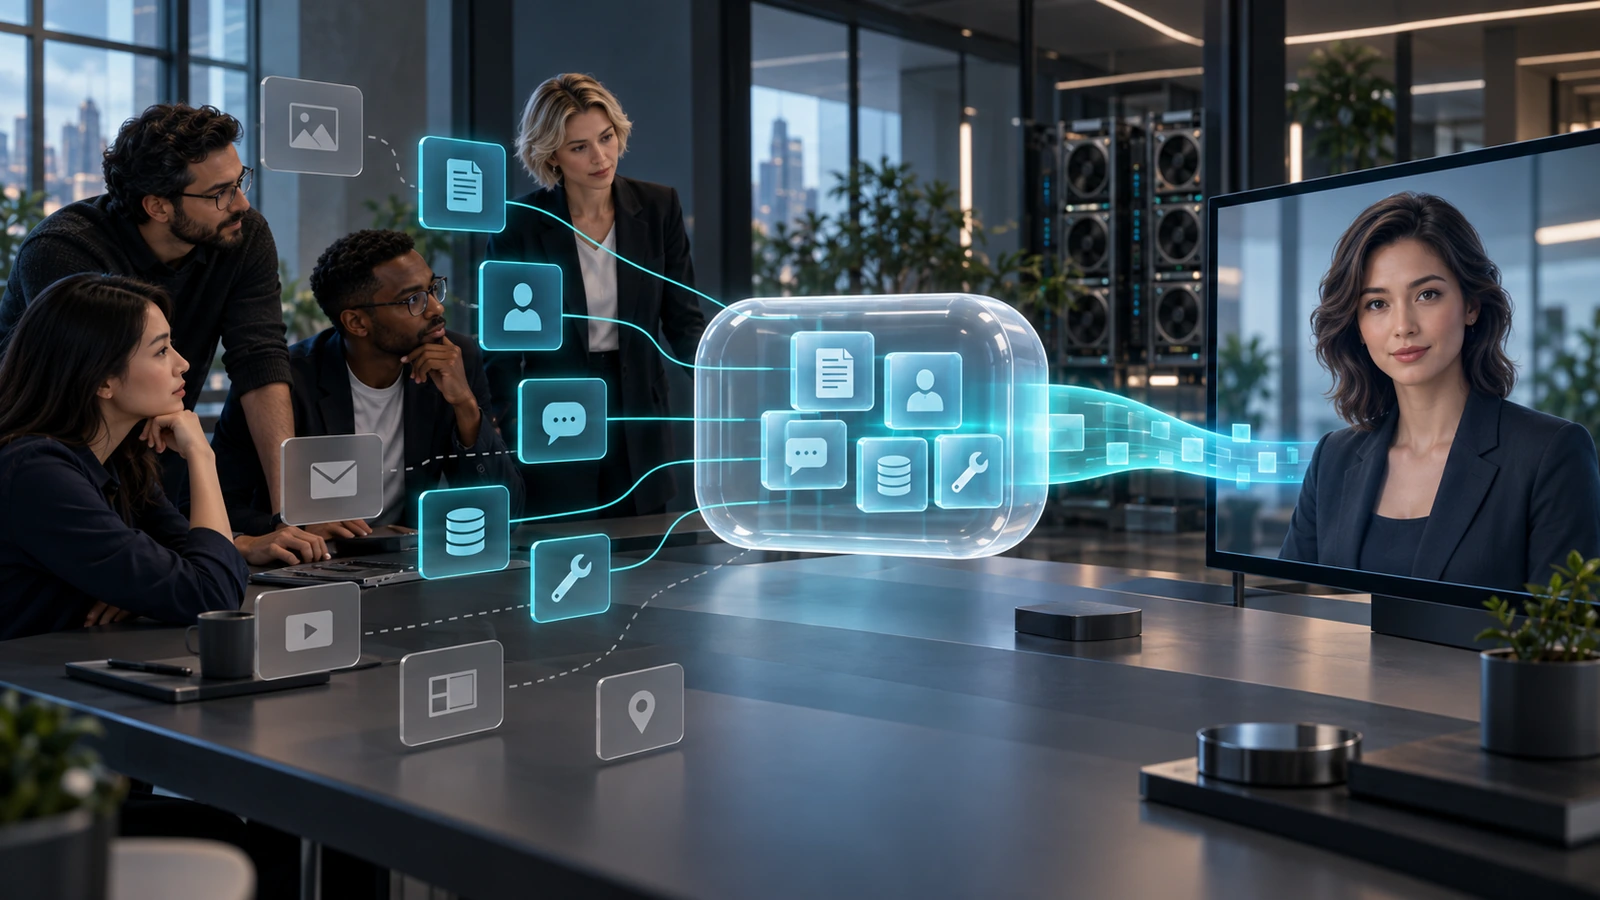
Context engineering for AI agents is the discipline of deciding what the model is allowed to see on each turn. For a real-time avatar in a bank, government service or regulated enterprise, the safest pattern is to assemble a governed “turn packet”: the smallest set of approved instructions, identity attributes, conversation state, retrieved evidence, tool definitions and live observations needed for the current response.
This is a runtime control, not simply a better system prompt. A good turn packet carries provenance, permission and expiry metadata; excludes unnecessary personal or cross-tenant data; and stays within a deliberate token and latency budget. A larger context window does not remove those responsibilities. It merely creates more space in which stale, conflicting or unauthorised information can hide.
Context engineering is not another name for RAG
Prompt engineering improves the wording and structure of instructions. Retrieval-augmented generation (RAG) finds relevant knowledge. Memory persists selected facts or summaries. Model routing chooses which model should handle a request. Context engineering decides how those elements are assembled for one model invocation—and what must stay out.
That distinction matters in production. A retrieval system can return the correct document but still expose a passage the user may not see. A memory system can recall an accurate preference that has expired or belongs to another role. A carefully written prompt can still be displaced by contradictory tool output. The problem is not only whether information is relevant. It is whether it is authorised, current, trustworthy and necessary now.
Anthropic describes context as a critical but finite resource and recommends curating the smallest high-signal set of tokens needed for the desired behaviour. Microsoft’s enterprise context-engineering analysis similarly frames it as the recurring decision about what enters an agent’s context window on each turn. The OpenAI Agents SDK documentation also separates application-local context from the information actually sent to the model—a useful architectural boundary, because identity and policy data need not automatically become model-visible text.
Build an eight-source avatar turn packet
A real-time avatar has more context sources than a text chatbot. Speech, interruptions, visible cues and live actions all compete with policies, knowledge and conversation history. Treating them as one undifferentiated prompt makes assurance difficult. A practical turn packet has eight separately governed sources.
1. Role, policy and disclosure
Include the avatar’s permitted purpose, response boundaries, disclosure wording and escalation rules. Version this layer and make non-negotiable controls distinguishable from style guidance. A friendly tone must never outrank a restriction on financial advice, identity claims or access to records.
2. Authenticated identity and entitlements
The packet may need a tenant identifier, user role, language and verified permissions. Prefer opaque identifiers and derived claims over raw identity records. Keep the full authorisation object outside the model where possible; expose only the minimum decision the model needs. Tool and data services must still enforce their own authorisation rather than trusting model-generated arguments.
3. Current task and user turn
Carry the latest utterance, detected language and the bounded task being attempted. Speech-recognition confidence or ambiguity can be useful, but a low-confidence transcript should trigger clarification rather than being treated as certain fact.
4. Conversation state
Include the recent exchanges and a structured summary of older state. Preserve commitments, unresolved questions and consent choices. Drop filler, duplicate confirmations and obsolete tool results. Compaction is itself a controlled transformation: test that it does not remove a prohibition, change a number or convert a tentative statement into a fact.
5. Retrieved enterprise knowledge
Pass only the passages needed for this turn, with source, version, classification, access decision and freshness. The design should complement a secure on-premise RAG architecture, not assume that semantic similarity is permission. Retrieved content is data, not an instruction, so isolate it from the system policy and defend against prompt injection embedded in documents.
6. Available tools and action scope
Expose the smallest appropriate tool set, with concise schemas and explicit limits. A citizen-information avatar does not need a payment tool merely because the wider platform supports one. An authenticated banking assistant may need a balance lookup while a public kiosk must not. Use a separate action gateway for secure tool calling; context selection does not replace approval, validation or transaction controls.
7. Live workflow and tool state
Return structured results, status and error conditions rather than entire service payloads. Mark whether a value is confirmed, pending, failed or simulated. Retain references to authoritative records so the model does not become the system of record.
8. Multimodal observations
A real-time avatar may receive transcript timing, interruption signals, microphone state, captions, screen state or deliberately scoped visual cues. Each needs a declared purpose. A camera feed should not silently become a broad source of demographic, emotional or identity inference. Where a signal is unnecessary, do not collect it or admit it to the packet.
Apply six gates before anything enters context
Each candidate item should pass the same admission process. This makes context assembly reviewable rather than an accumulation of application shortcuts.
- Identity and boundary: Which tenant, user, session and role does this item belong to?
- Necessity: What decision in this turn requires it? “It might be useful” is not enough for sensitive data.
- Permission: May this user, avatar role and model workflow access it for this purpose?
- Provenance: Which source and version produced it, and is it authoritative, inferred or user-supplied?
- Freshness: When was it valid, when must it be rechecked and when does it expire?
- Budget: Does its expected value justify the tokens, preprocessing and latency it adds?
These gates should run before ranking or compression wherever possible. Otherwise, an unauthorised passage can influence a summary even if the original text is removed later. Yepic’s AI data-classification framework provides a useful upstream policy for deciding which data classes may enter which deployment and processing path.
Make precedence explicit
Conflicts are inevitable. A retrieved procedure may be older than a current policy. A user may ask the avatar to ignore its role. A tool result may contain text that looks like an instruction. Define precedence before deployment: approved system policy and safety constraints first; authenticated entitlements and the current task next; current authoritative business data after that; then conversation history, memory and observations.
Untrusted content should never be promoted into the instruction layer. Label sources in a machine-readable structure and keep policy, evidence and user content in distinct fields. If two authoritative sources disagree, the correct response is often to stop, explain the conflict and escalate—not to let the model improvise a winner.
Budget for attention and spoken latency
A real-time conversation exposes the cost of context engineering immediately. Retrieval, filtering, redaction, summarisation and prompt construction all happen before or during generation. They contribute to the pause a user hears.
Define a budget by function rather than filling the available window. Reserve capacity for mandatory policy, the current turn and output. Allocate bounded slices to retrieved evidence, recent history, tool descriptions and live state. When demand exceeds the budget, use deterministic priorities: remove duplicate evidence, replace old turns with a tested summary, load detailed tool instructions only when relevant, or ask a clarifying question.
Do not optimise token count alone. A smaller packet that omits a critical exception is worse than a slightly larger one. Measure successful task completion, groundedness, permission errors and end-to-end response time together. Anthropic’s context-engineering guidance emphasises this attention budget; Microsoft’s September 2026 analysis also notes that more context can add cost while making the right fact or tool harder to select.
Record the decision without logging the conversation
Teams need to reconstruct why the avatar had access to particular information without retaining every utterance indefinitely. For each turn, record a privacy-minimised context manifest:
- pseudonymous session and tenant references;
- turn-packet schema and policy versions;
- source identifiers, versions and classifications;
- permission decisions and excluded-source reason codes;
- redaction and compaction transformations;
- token allocation and expiry values;
- model, tool and knowledge versions; and
- output, action and escalation references.
This aligns with a privacy-minimised AI audit trail: retain evidence about the decision path, not a default copy of all customer content. Apply legal, records and sector requirements to the manifest itself.
Test the context compiler, not just the model
A golden set for context engineering should include positive and negative cases. Confirm that a required policy appears, an unauthorised record does not, a revoked entitlement takes effect, stale knowledge is rejected and a malicious instruction inside a retrieved document remains inert. Test cross-tenant names, multilingual turns, interrupted speech, long conversations, tool failures and summaries produced at different compaction thresholds.
Useful measures include must-use fact recall, forbidden-context absence, source attribution, permission precision, contradiction handling, token volume and time added before first audio. Re-run the suite whenever policies, retrieval, memory, tool schemas, models or summarisation change. A versioned avatar evaluation dataset can hold these release cases.
Choose the deployment boundary deliberately
Public cloud, private cloud, sovereign cloud and customer-hosted deployments can all support governed context engineering. The right choice depends on data classification, latency, integration, operational capability, procurement and jurisdiction.
A customer-hosted design can keep context assembly, retrieval, model inference and evidence services within the customer’s environment and on its GPUs, subject to a properly scoped implementation. It can also integrate directly with internal identity and knowledge systems. But location does not make the packet correct: access controls, source hygiene, expiry, isolation and testing still have to be engineered and operated. Cloud services may offer faster managed updates and elastic capacity; private or sovereign architectures may provide a useful compromise.
Yepic develops proprietary talking-photo and real-time avatar technology and can support cloud, private-cloud and custom private or on-premise architectures. Its Abu Dhabi Aviation and Oracle integration shows the practical work around development and production environments, APIs, iframe integration, real-time streaming, captions, microphone behaviour, WebRTC testing, browser remediation and cybersecurity support. It is relevant integration evidence, not a claim that this was a completed customer-hosted context-engineering deployment.
Twelve questions for architecture review
- Which eight sources can contribute to a turn, and who owns each one?
- Which identity and authorisation decisions remain outside the model?
- How are tenant, role and session boundaries enforced before retrieval or summarisation?
- How are policy, evidence, user content and tool output structurally separated?
- What provenance, version, classification and expiry fields accompany each item?
- Which data and observations are explicitly forbidden from context?
- How are conflicts and missing authoritative data handled?
- What is the token and pre-generation latency budget for each source?
- How are history and tool results compacted, and what must never be summarised away?
- Which context decisions are recorded without retaining excessive personal content?
- Which negative tests prove that forbidden, stale and cross-tenant data stay out?
- Which changes trigger re-evaluation and approval?
Start with one turn, not the whole platform
Choose one bounded workflow, two user roles and three data classes. Draw the candidate sources, apply the six gates, define precedence and set the turn-packet budget. Then test both what the avatar must know and what it must never receive. That exercise produces a far more useful architecture review than asking whether the model has a large enough context window.