AI Model Risk Management for Avatars: Govern the Whole System
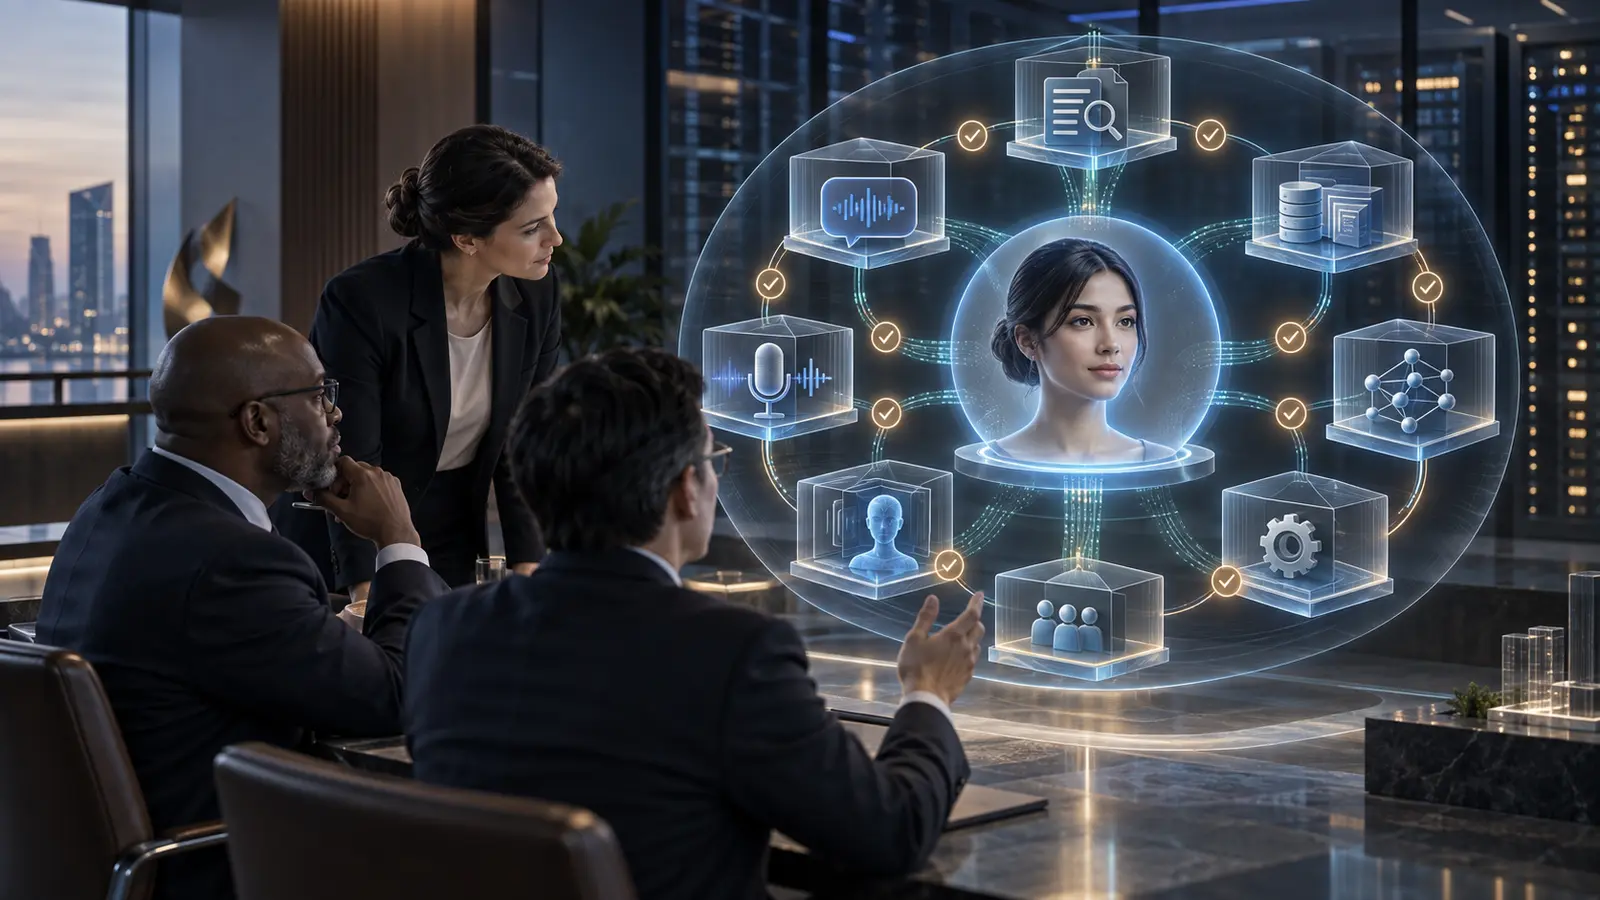
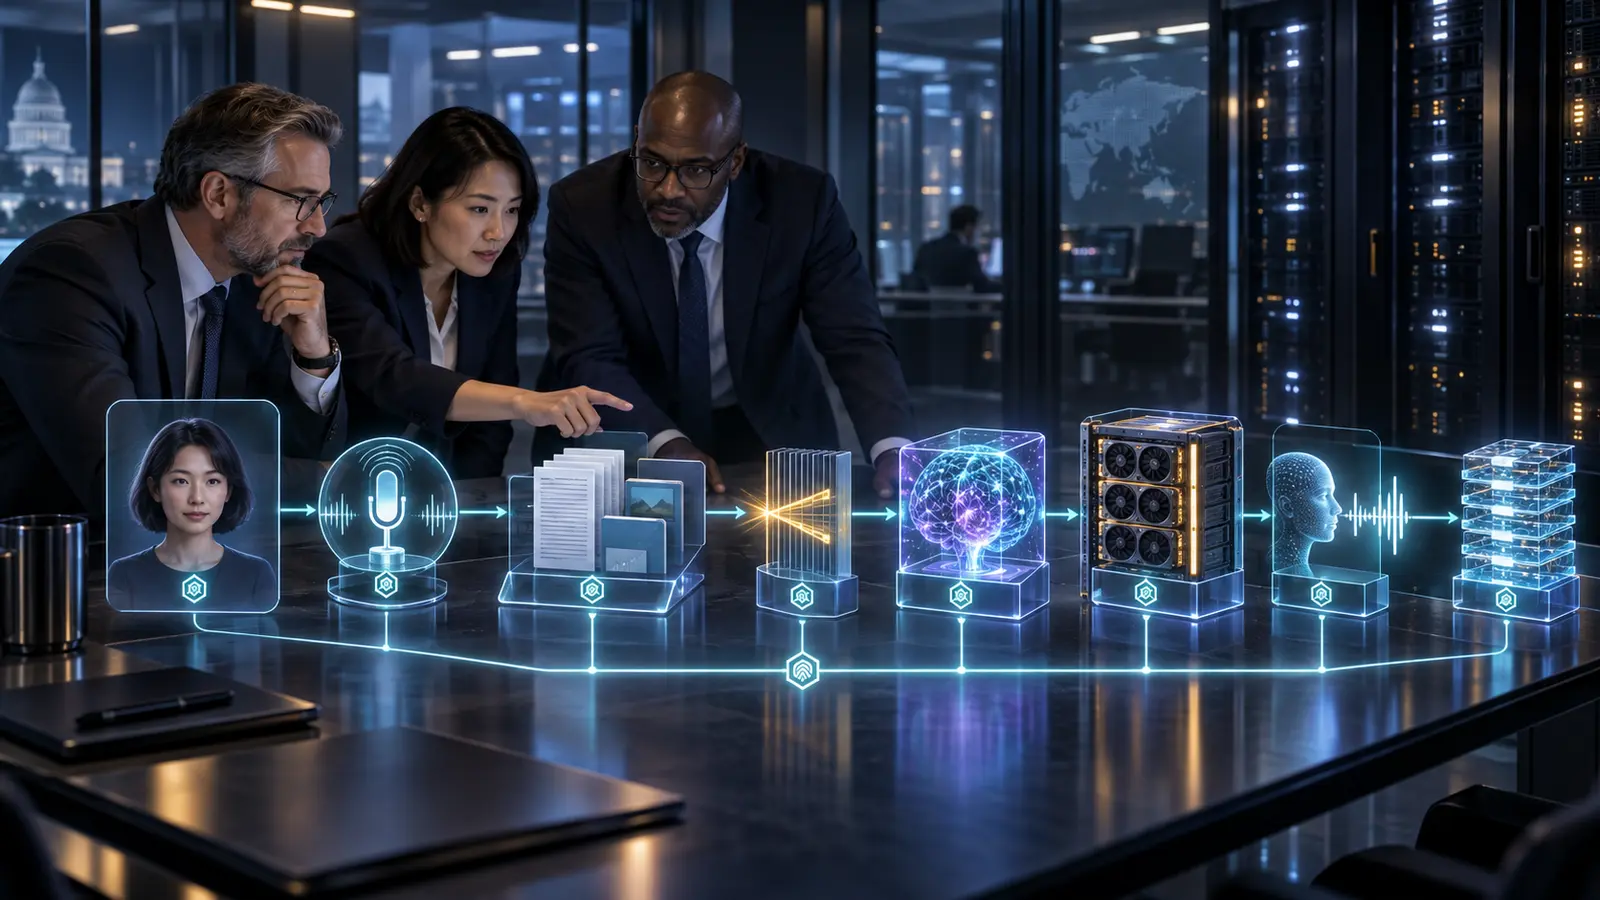
AI model risk management for a real-time avatar should govern the whole decision chain, not just the large language model. A bank may have separate speech, retrieval, reasoning, policy, voice and rendering models, plus deterministic services and external business systems. Each component needs an explicit classification, owner and control path; the composite use case then needs its own assessment because individually acceptable components can create material risk when connected.
The practical starting point is a two-level inventory: one record for every model or material component, and one record for the end-to-end avatar service. Apply validation, monitoring and change controls in proportion to what the service can see, say and do. Do not force every component into a regulatory definition of “model”, but do not let a narrow definition leave consequential AI outside governance.
This guide provides an eight-part system map, six validation lenses, a model-risk record and twelve review questions for regulated buyers. It complements Yepic’s AI bill of materials for avatar dependencies: the bill records what is in a release; model risk management determines how much challenge, evidence and oversight each element and use case require.
Start with scope, not a compliance label
“Model” does not mean the same thing in every policy or jurisdiction. A model-risk team, AI governance forum, operational-risk function and privacy office may draw different boundaries. Resolve that deliberately.
The current UK Prudential Regulation Authority SS1/23 supervisory statement sets five principles covering identification and classification, governance, development and use, independent validation, and mitigants. It applies to specified PRA-regulated firms and states that its principles extend across model and risk types, including externally developed models and AI in modelling techniques to the extent the expectations apply more generally.
The US position must be described differently. Revised interagency guidance issued on 17 April 2026 is risk-based and tailored, but its definition covers quantitative methods grounded in statistical, economic or financial theory. It explicitly says generative and agentic AI are outside that guidance’s scope, while noting that banks’ wider governance should determine appropriate controls for excluded systems. The Federal Reserve’s published guidance is therefore useful context, not a basis for claiming that it directly governs an avatar’s generative components.
Create a scope decision record before procurement or pilot approval. For each component, state whether it is:
- in the formal model inventory;
- covered by a separate AI, software, operational-risk or third-party framework;
- deterministic infrastructure rather than a model; or
- unresolved and awaiting a named policy owner’s decision.
“Not a model” is a routing decision, not a risk exemption.
Map eight risk objects across the avatar system
A real-time avatar is a system of systems. Map at least these eight objects, even if local policy classifies some outside formal model risk management.
1. Speech and language understanding
Automatic speech recognition, language detection and translation can alter the user’s meaning before the reasoning system sees it. Validate accents, dialects, code-switching, domain vocabulary, noise, interrupted speech and confidence handling. A plausible transcript can still be materially wrong.
2. Retrieval and ranking
Embedding, search and reranking models determine which evidence enters context. Assess permission filtering, source freshness, coverage, relevance and failure behaviour. A good language model cannot repair a retrieval layer that omitted the governing policy or exposed another customer’s document.
3. Reasoning and generation
Record the exact model family, version or immutable service identifier, intended uses, prohibited uses, decoding controls and known limitations. Test factual support, instruction hierarchy, multilingual behaviour, refusal, uncertainty and susceptibility to adversarial context. Benchmark the use case, not the model’s marketing score.
4. Guardrails and classifiers
Safety classifiers, PII detectors, topic routers and policy gates are models too when they infer categories probabilistically. Measure false accepts and false rejects against real operating conditions. Yepic’s guide to enforceable avatar guardrails explains why prompts alone should not carry authorisation or transaction control.
5. Tools and business actions
A tool selector may propose a search, booking, record update or payment step. Validate selection accuracy and argument construction, but keep final authorisation in a deterministic gateway wherever the consequence warrants it. Model confidence is not permission.
6. Voice and speech synthesis
Text-to-speech affects intelligibility, identity, emphasis and perceived certainty. Test names, numbers, currencies, dates, disclosures and multilingual pronunciation. Record the licensed voice asset and approved persona separately from the synthesis model.
7. Avatar rendering and perception
Rendering influences lip synchronisation, turn-taking and non-verbal cues. Camera or emotion-sensing components can add separate accuracy, fairness and privacy risks. Do not treat expressive presentation as proof that the underlying answer is correct.
8. The composite service
Finally, assess the assembled system. Latency can cause interruptions; transcription can distort retrieval; translation can weaken guardrails; a correct answer can be delivered with misleading emphasis; and a safe response can become unsafe when paired with an overpowered action tool. Aggregate risk lives in these interactions.
Classify materiality by consequence and exposure
Do not assign risk tier from model size or novelty alone. Use the business service to evaluate:
- Consequence: could an error affect money, legal rights, safety, access to services or a regulated disclosure?
- Authority: can the system only explain, or can it prepare, approve or execute an action?
- Exposure: how many people, transactions, languages and channels depend on it?
- Data sensitivity: does it process public information, employee data, account information, health data or classified material?
- Detectability and reversibility: would an error be noticed before harm, and can the outcome be corrected?
- Dependency concentration: do several services rely on the same model, provider, dataset or GPU runtime?
Tier both the component and the use case. The same speech model may be low materiality in a public museum guide and high materiality when capturing instructions for a banking transaction. The current US interagency guidance similarly distinguishes inherent risk, exposure, purpose and use for models within its scope and asks banks to consider aggregate dependencies. That is a useful design principle even where the guidance does not cover generative AI.
Build one model-risk record that joins the evidence
For each governed component, record its owner, supplier, purpose, users, inputs, outputs, data provenance, assumptions, limitations, environments, dependencies, materiality, validation status, performance thresholds, monitoring, change authority, fallback and retirement trigger.
For the composite avatar, add the approved knowledge sources, action boundary, supported languages, expected load, human-oversight mode, deployment location and the identifiers of every contributing component. Link the record to the exact release rather than a mutable label such as “production”. Yepic’s runtime-fingerprint approach to AI reproducibility shows how model, policy, knowledge and infrastructure evidence can be tied to what actually handled a session.
The inventory should also expose common dependencies. A single translation model, vector index or vendor endpoint may sit beneath several apparently independent avatars. Portfolio reporting that counts models but hides concentration gives false comfort.
Validate through six independent lenses
Validation should be proportionate, technically competent and able to challenge the delivery team. It need not mean one central function performs every test. It does mean the reviewer has enough independence, evidence and authority to contest the result.
- Purpose and conceptual soundness: is the component suitable for the stated task, population, language and decision boundary?
- Data and provenance: are evaluation data relevant, lawful, representative and separated from training or tuning data where required?
- Performance: are accuracy, grounding, refusal, latency and quality measured against use-case thresholds and meaningful baselines?
- Controls: do permissions, policy gates, transaction checks, human handover and safe states still work when the model is wrong?
- Integration: do error propagation, timeouts, retries, version mismatches and cross-model interactions create new failure modes?
- Human factors: can users and operators recognise limitations, contest output, recover from errors and avoid overreliance on a human-like presentation?
NIST’s AI Resource Center supports testing, evaluation, verification and validation under its voluntary AI Risk Management Framework. Its framework is not a bank-specific rule and is currently being revised, but it provides a useful cross-sector vocabulary for teams whose governance extends beyond formal model-risk policy.
Turn limitations into enforceable operating conditions
A limitations register is useful only when it changes behaviour. Convert each material limitation into one or more operating conditions: restrict a language or channel, narrow the knowledge scope, require confirmation, reduce transaction authority, route to a human, add a deterministic calculation, increase monitoring or stop service.
Define who accepts residual risk, for how long and with what evidence. An exception should include an owner, rationale, compensating control, expiry date and closure criterion. “Vendor roadmap” is not a control.
Ongoing monitoring should combine component measures with service outcomes. Watch speech confidence, retrieval coverage, unsupported answers, policy interventions, action denials, user corrections, handovers, complaints and performance by language or channel. Avoid retaining raw conversations merely because they are easy to collect; design privacy-minimised evidence that still supports review.
Make every change answer a revalidation question
Model updates are only one change class. A new prompt, retrieval corpus, embedding model, policy threshold, voice, supported language, GPU precision, browser, action API or traffic profile can alter risk.
Classify each change as editorial, configuration, component, interaction or use-case change. Predefine which tests must rerun and who can approve promotion. Emergency changes need a bounded exception, evidence capture and follow-up validation. Monitor the effective runtime because approved configuration and deployed configuration can diverge.
Deployment location changes evidence, not accountability
Customer-hosted deployment can keep selected models, data and telemetry inside the customer environment and integrate with internal validation, access-control and change processes. It also transfers more responsibility for GPU runtime, patching, monitoring, capacity and configuration evidence to the customer. On-premise does not make a model valid.
Private or sovereign cloud can combine dedicated tenancy or jurisdictional controls with managed infrastructure. The model-risk record should identify which party can change each component and what evidence the customer receives.
Managed public cloud may offer faster updates and stronger platform operations, but model versions or implementation details may be less controllable. Buyers should contract for change notice, version evidence, monitoring access and exit where those are material.
Choose the architecture that can meet the use case’s risk, latency, data and operating constraints. Yepic can scope cloud, private-cloud, sovereign and customer-hosted avatar systems, including deployments on customer-controlled GPUs where appropriate; the exact component and responsibility split requires custom implementation.
Take twelve questions into the model-risk meeting
- Which components fall inside formal model policy, and who governs those outside it?
- What is the end-to-end use case, decision boundary and worst credible outcome?
- Which model, data or provider dependencies are shared across services?
- How were component and composite materiality determined?
- What evidence supports each intended language, channel and user population?
- Which limitations are converted into technical operating conditions?
- Who performed effective challenge, and what issues remain open?
- What thresholds trigger restriction, human handover or shutdown?
- Can the team reconstruct the exact release and policy that handled a session?
- Which changes require partial or full revalidation?
- How are vendor components validated when code or training data are unavailable?
- Who accepts residual risk, and when does that acceptance expire?
Make the integration itself a governed object
Yepic’s Abu Dhabi Aviation and Oracle enterprise avatar integration connected enterprise data, APIs, an iframe, real-time streaming, captions, microphone behaviour, WebRTC testing, browser remediation and cybersecurity support across development and production environments. It shows why a real avatar service has more risk-bearing parts than the visible face or the LLM.
That case study is not presented as a completed customer-hosted model-risk implementation. The transferable lesson is architectural: give the assembled service an owner, inventory its components and dependencies, validate the interactions, and preserve evidence through change.
Before approving a pilot, ask the supplier, model-risk team and service owner to review the same system map. If they cannot agree which components exist, which policy owns them, what would make them material and which evidence permits production use, the organisation is not yet managing model risk—it is distributing it.