LLM Semantic Caching for Avatars: Decide What May Be Reused
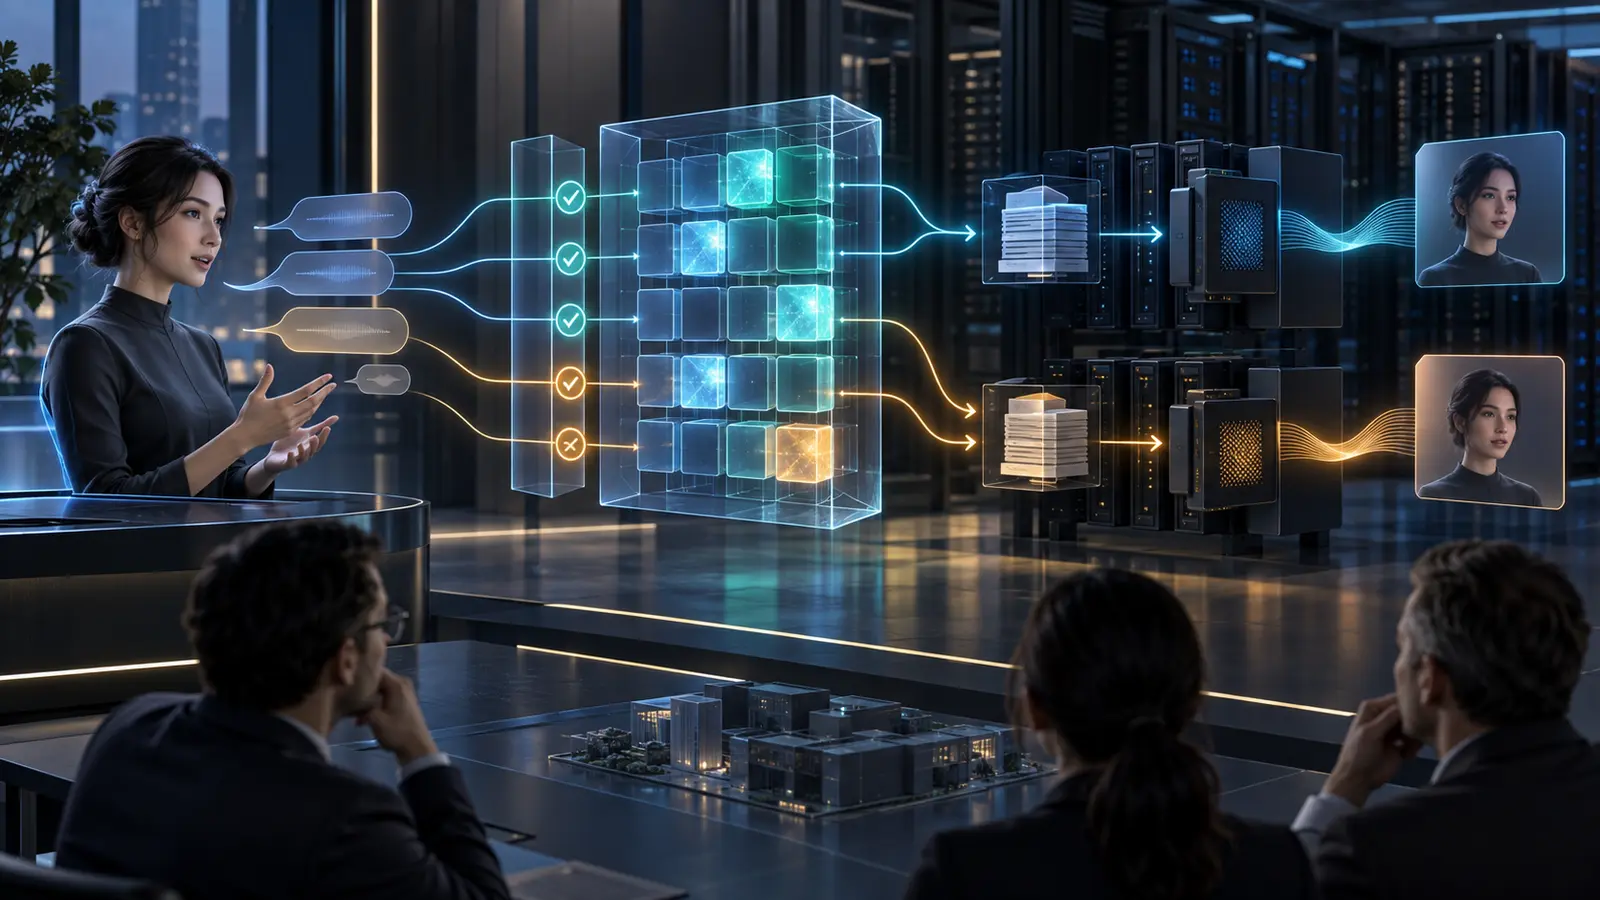
An LLM semantic cache should reuse an avatar response only when the new request matches more than meaning. It must also match the authorised tenant and user scope, the relevant knowledge and policy versions, the language and channel, the required freshness, and the consequence of being wrong. If any of those conditions differ, the system should retrieve and generate a fresh answer.
That is the central design decision for banks, governments and regulated enterprises. Semantic caching can reduce repeated inference and shorten response time, especially when thousands of people ask variations of the same question. But a similar sentence is not proof that two users are allowed to receive the same answer. A fast cache hit can still be stale, cross a tenant boundary or bypass a newer policy.
The practical answer is to place a policy gate before the cache, define a reusable-answer contract and make bypass an expected outcome—not an error. This guide explains how.
First, separate four kinds of cache
“LLM caching” can describe materially different mechanisms. Architecture reviews should name the object being reused rather than treating cache as one feature.
1. Static asset caching
An avatar service may cache approved visual assets, pronunciation resources, configuration or other largely static material. Normal content-delivery and application-cache controls apply, including versioning and invalidation.
2. Prompt, prefix or KV caching
This reuses computation for an identical prompt prefix, such as a long system instruction or document context. It does not normally return a stored final answer. For example, vLLM Automatic Prefix Caching reuses the KV cache when a new request shares an existing prefix. Amazon Bedrock prompt caching similarly targets repeated prompt prefixes and documents that cache hits are best effort and model-dependent.
This distinction matters: prefix caching may reduce prefill work, but the model still processes the new suffix and generates a response.
3. Exact response caching
An exact response cache returns a previous result when a deterministic key matches. NVIDIA Triton, for example, documents a response cache keyed by a hash that includes the model name, model version and model inputs. This can avoid model execution for a duplicate request, although the application must still decide whether that key captures every relevant business condition.
4. Semantic response caching
A semantic cache embeds the incoming request and looks for a sufficiently similar stored request. On a hit, it may return the earlier answer even though the wording is different. “When does the branch close?”, “What time are you open until?” and “Can I visit after 5?” may express the same intent.
This is the highest-risk class because similarity deliberately widens the reuse boundary. It can be valuable for public, stable, low-consequence information. It requires much tighter controls for personalised, regulated or action-taking conversations.
Use a reusable-answer contract
Do not let a similarity threshold make the whole decision. Each cache entry should carry a contract describing the conditions under which the response may be reused. At minimum, record:
- Security scope: tenant, application, environment and data-class boundary.
- Audience scope: anonymous, authenticated, role-limited or individually entitled.
- Knowledge scope: source identifiers, retrieval-index version and source snapshot.
- Runtime scope: model, system prompt, tool, guardrail and policy versions.
- Interaction scope: language, locale, channel and accessibility mode.
- Freshness scope: creation time, expiry time and event-based invalidation rules.
- Consequence scope: informational, advisory, approval-requiring or action-taking.
- Evidence: original request, match score, reuse decision, response identifier and reason for bypass.
This extends the principles in Yepic’s on-premise RAG architecture: permission filtering must happen before information reaches the generation context. With a semantic cache, the same principle applies before a stored answer is released.
Put five gates in front of every semantic hit
Gate 1: identity and tenant
The cache lookup should begin inside the caller’s security domain. Tenant, environment and application must be part of the namespace—not optional metadata checked after retrieval. Anonymous public-service content can use a broader scope; authenticated banking or employee content should not.
This is one application of the isolation model described in multi-tenant AI security for avatar sessions. A shared physical cache may be technically efficient, but its logical keys, encryption and access controls still need to prevent cross-tenant discovery and reuse.
Gate 2: permission and data class
Re-evaluate the current user’s entitlement before returning the response. Do not assume that the permission attached to the original request is still valid. A cached answer derived from internal policy, a customer account or a restricted knowledge base must not become public because a later query sounds similar.
The cache policy should consume the same classifications and access decisions used by retrieval. Yepic’s guide to AI data classification explains how component, location, retention and egress rules can follow the information through the system.
Gate 3: intent and semantic fit
Only now should the system test similarity. The evaluation set must include near-neighbour traps: negation, changed dates, changed amounts, different products, different jurisdictions and questions that share vocabulary but require different answers. “Can I transfer £10,000?” is not safely equivalent to “Can anyone transfer £10,000?”
Similarity thresholds are workload-specific. A universal number would be misleading because embedding models, languages, query lengths and risk tolerances differ. Low confidence should trigger a fresh path or a clarifying question.
Gate 4: version and freshness
A time-to-live is necessary but insufficient. Invalidate entries when a source changes, a permission is revoked, a policy is approved, a prompt or model is released, an embedding model changes, a retrieval index is rebuilt, or an incident demands a forced purge. Version identifiers should be part of the cache key or eligibility check.
For volatile answers—balances, flight status, eligibility, pricing, emergency information or live service availability—the correct policy may be “never semantically cache”. A user request for the latest position should also force recomputation.
Gate 5: consequence and action
A cached answer must not inherit authority to perform a business action. If the avatar can book, pay, approve, update a record or disclose personalised information, the action gateway should perform fresh authentication, authorisation, validation and confirmation. The conversational layer may reuse low-risk explanatory language; it should not replay a previous transactional outcome.
Create an explicit bypass list
A design is safer when teams specify what must not be reused. Begin with:
- account, patient, employee or citizen-specific responses;
- live balances, prices, availability, timetables and operational status;
- eligibility, underwriting, diagnostic or legal conclusions;
- responses containing one-time tokens, identifiers or secrets;
- requests that can trigger tools or change a system of record;
- low-confidence speech recognition, code-switching or ambiguous language;
- sessions with changed identity, role, consent or accessibility needs; and
- any entry whose source, model, prompt, guardrail or policy version is no longer current.
The bypass route must remain fast enough to preserve a natural conversation. Semantic caching should be one optimisation inside the latency budget, not a dependency that makes uncached sessions unusable.
Test for false reuse, not just cache hits
A high hit rate can be a failure if the cache returns plausible but unauthorised answers. Report performance and correctness together:
- eligible-request rate and cache-hit rate;
- false-reuse and stale-hit rate;
- cross-tenant or cross-entitlement hits, with zero as the acceptance target;
- p50 and p95 response-time change for hit, miss and bypass paths;
- invalidation propagation time;
- compute avoided after cache lookup overhead; and
- answer-quality change by language, accent, channel and user group.
The test corpus should cover paraphrases, negation, number and date changes, similar product names, permission changes, tenant crossover, stale versions, deletion events, multilingual queries and adversarial inputs. A 2026 research paper on key-collision attacks against LLM semantic caching demonstrates why intentional collision and response-hijacking tests belong in the plan. Its reported results describe the authors’ experimental systems, not a universal vulnerability rate.
Run the same tests under concurrent load. A cache that is correct in isolation can still show race conditions during invalidation, replication or failover. Yepic’s end-to-end AI load-testing method provides the wider conversation path: speech, retrieval, reasoning, voice, rendering and WebRTC must be measured together.
Choose the deployment boundary deliberately
Managed cloud prompt caching can reduce implementation work, but the buyer should verify supported models, regions, time-to-live behaviour, usage visibility and which content the provider retains or processes. Provider-managed prefix caching is not the same as an application-controlled semantic response cache.
A private-cloud or customer-hosted cache gives the enterprise more direct control over storage location, keys, network paths, invalidation and audit evidence. It also makes the customer responsible for capacity, high availability, patching, backup policy and secure disposal. On-premise does not make a cache correctly scoped by default.
Yepic can scope real-time avatar deployments for cloud, private-cloud and customer-hosted environments, including commercial-GPU optimisation and integration with enterprise services. The correct boundary depends on data classification, latency, operational ownership and supplier constraints. It should be decided component by component.
The Abu Dhabi Aviation and Oracle integration is useful evidence of the wider engineering discipline: development and production environments, API and iframe integration, streaming, captions, microphone behaviour, WebRTC testing, browser remediation and cybersecurity support all mattered. It is not presented as a customer-hosted or semantic-caching implementation.
Twelve questions for the architecture review
- What exactly is cached: assets, prefixes, retrieval results, model outputs or complete responses?
- Which tenants, environments and applications can share a namespace?
- Is current authorisation checked before every response is released?
- Which data classes and use cases are ineligible?
- What model and threshold judge semantic similarity, and how were they evaluated?
- Which source, index, model, prompt, tool and policy versions bind the entry?
- What time-based and event-based rules invalidate it?
- Can an operator purge one entry, user, tenant, source or version?
- How are multilingual queries, numbers, negation and ambiguous speech tested?
- Can a cached response ever reach an action gateway without fresh checks?
- Which metrics expose false reuse, stale hits and cross-boundary access?
- Does the miss and bypass path still meet the conversation’s service objective?
Start with a narrow, reversible cache
The strongest first use case is usually a bounded set of public, stable, high-volume questions with clear source ownership. Build the reusable-answer contract, test near-neighbour failures, exercise invalidation, measure end-to-end latency and expand only when evidence supports the next class of content.
For a regulated avatar, the goal is not the highest possible hit rate. It is the largest set of responses that can be reused without weakening permission, freshness, accuracy or accountability. Yepic can help architecture teams map that boundary across the avatar, speech, knowledge, model, policy and rendering stack for a properly scoped deployment.