AI Assurance for Avatars: Turn Claims Into Evidence
AI assurance should turn a supplier’s claims into a traceable argument that a specific avatar service is acceptable for a defined use, environment and period of time. It is not a security questionnaire, a model benchmark or a one-off compliance badge. For a bank or public body, the useful output is a living assurance case: each material claim is linked to evidence, assumptions, limitations, an owner and a trigger for review.
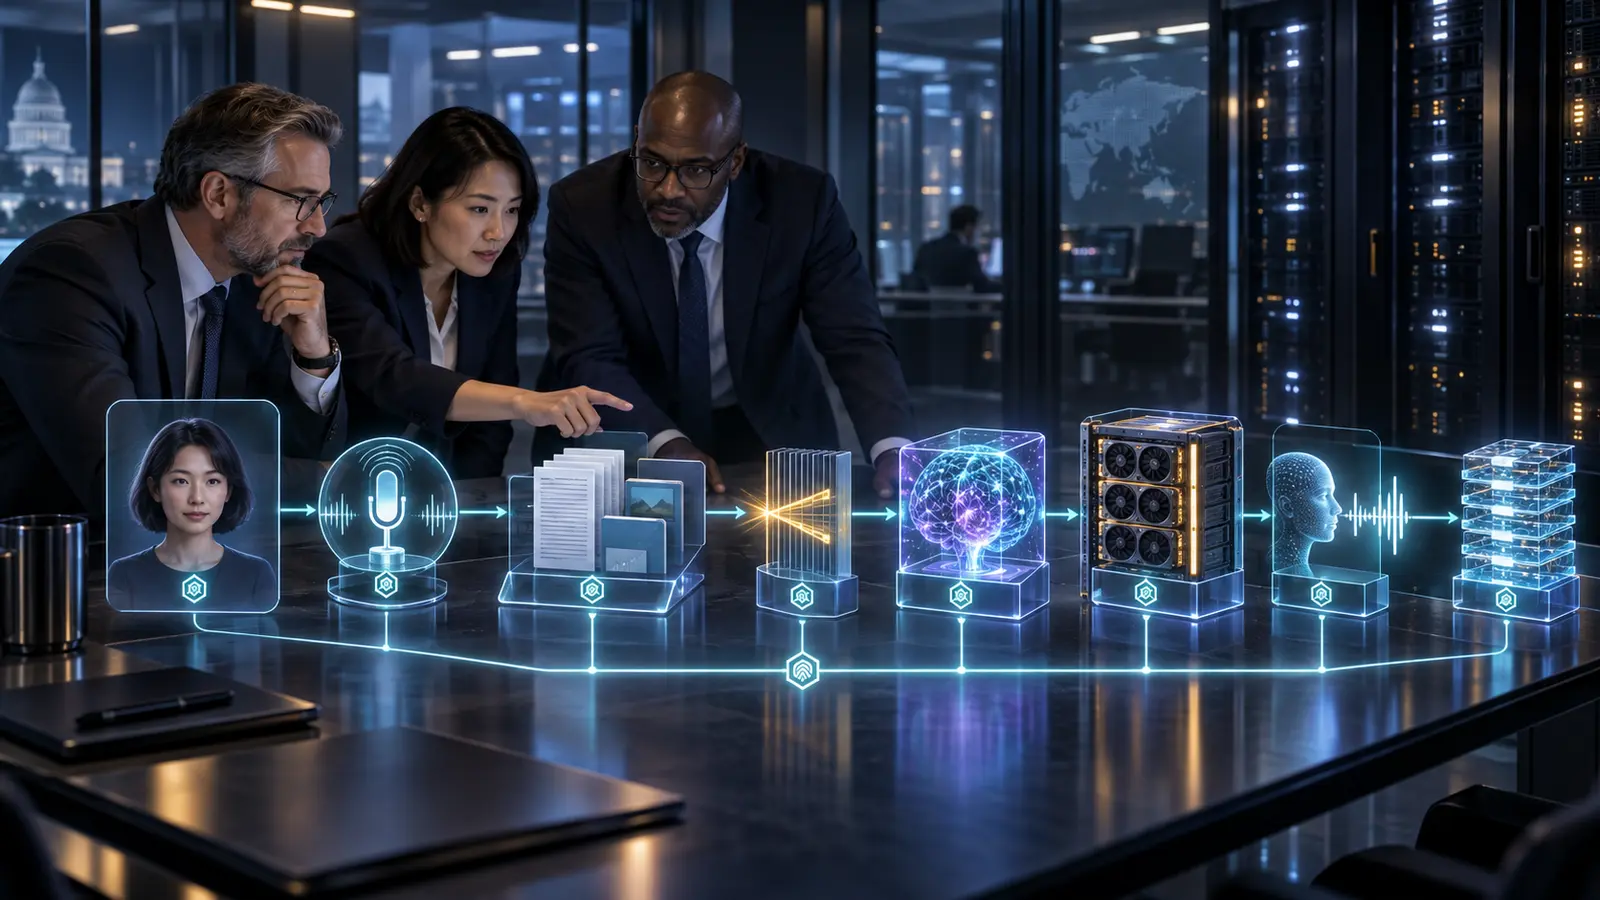
That matters because a real-time avatar is a system of systems. Speech recognition can alter a user’s meaning; retrieval decides which source reaches the model; policy gates restrict what may be said or done; voice and rendering shape how certainty is perceived; business APIs can create real consequences. A test report for the language model proves little about that assembled service.
This guide gives architecture, risk and procurement teams a practical structure: one bounded top-level claim, seven supporting claims, an evidence record, explicit challenges and twelve questions for the production gate.
What AI assurance means in practice
The UK Department for Science, Innovation and Technology describes AI assurance as building confidence by measuring, evaluating and communicating whether an AI system meets relevant criteria. Its Introduction to AI assurance, published on 12 February 2024, places assurance within wider governance rather than treating it as a single technical test. The department’s portfolio of assurance techniques includes impact assessment, performance testing, audit and conformity assessment among a wider set of options.
An assurance case is the structure that explains how those activities support a decision. NIST’s work on structured software assurance cases describes a chain of claims, arguments and evidence, with assumptions and context made explicit. That pattern transfers well to avatars, provided it is applied to the complete socio-technical service rather than the visible face alone.
Keep four ideas separate:
- A claim states what must be true, for whom and under which conditions.
- An argument explains why the evidence supports that claim.
- Evidence is the dated, attributable result, record or artefact that can be reviewed.
- An assumption is a condition the argument depends on but has not itself proved.
“The avatar is secure” is too broad to test. “Release 4.2 prevents unauthorised account actions when used by authenticated retail-banking customers through the approved web channel” is narrower, testable and capable of being challenged.
Set the boundary before collecting evidence
An assurance case becomes misleading when its scope is vague. Record the service purpose, users, languages, channels, deployment locations, data classes, knowledge sources, business actions, human-handover route, expected load and prohibited uses. Identify the exact release and environment. A pilot that only answers public questions does not provide evidence for an authenticated service that can update customer records.
Then write a top-level claim that is deliberately conditional. For example:
Avatar service release 4.2 is acceptably trustworthy for providing approved policy information to authenticated employees in English and Arabic through the internal web channel, within the stated operating limits and residual-risk acceptance.
“Acceptably” does not mean risk-free. It means the relevant authority has defined tolerances, reviewed evidence and accepted the remaining risk for that use. Name that authority and put an expiry date on the decision.
Decompose the service into seven assurance claims
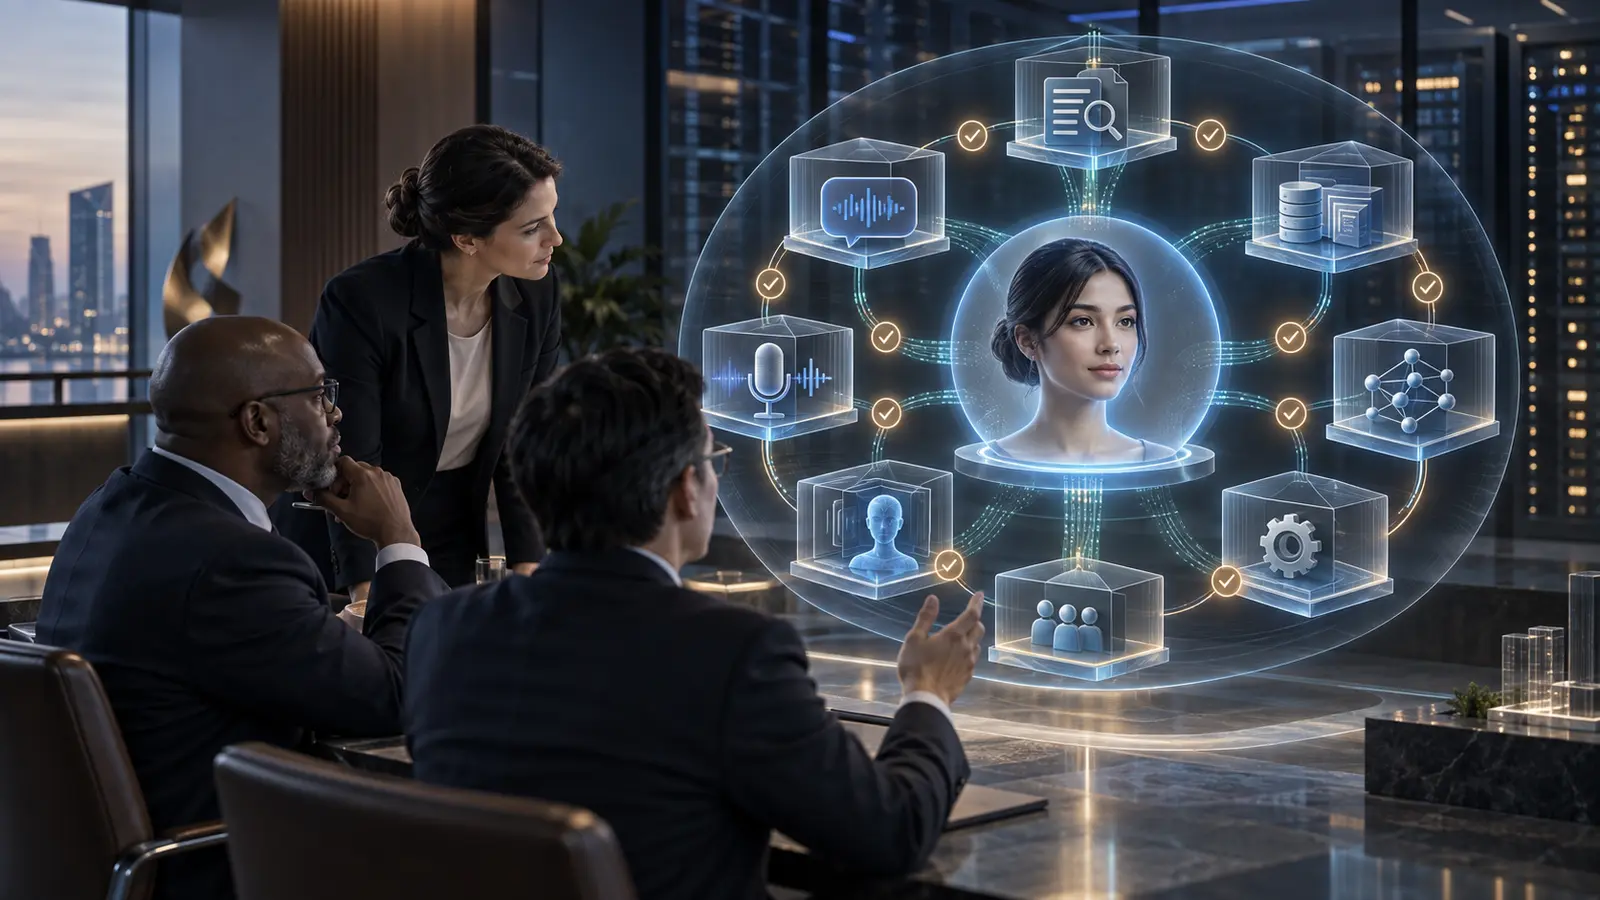
A useful avatar assurance case should cover at least seven domains. The exact hierarchy will vary by sector and consequence, but leaving one of these domains out usually leaves a material blind spot.
1. Identity and data are handled within the approved boundary
Claim that users, workloads and administrators are identified appropriately; permissions follow the session; sensitive data only reaches approved components; and retention, redaction and deletion behave as designed. Evidence may include data-flow reviews, access tests, configuration extracts, redaction evaluations and deletion receipts. Hosting location supports this claim only when the actual data paths and controls are shown.
2. Knowledge and responses are fit for the stated purpose
Separate retrieval quality from generated-answer quality. Evidence should cover source authority, freshness, permission filtering, coverage, citation or grounding behaviour, unsupported-answer handling and performance by language or user group. A benchmark from a model provider is not evidence that the customer’s knowledge corpus, prompt and retrieval policy work together.
3. Policy and action boundaries are enforceable
Show that prohibited topics, transaction limits, confirmation steps and tool permissions are enforced outside the model where consequences require deterministic control. Test direct requests, indirect prompt injection, malformed tool arguments, retries and partial failures. The claim should state what the avatar may explain, prepare, recommend, approve or execute.
4. Presentation does not mislead the user
The face and voice change the risk. Test disclosure that the user is interacting with AI, intelligibility, captions, interruption, turn-taking, pronunciation of names and numbers, and the effect of visual or vocal confidence. A fluent avatar can make a weak answer appear authoritative. Evidence should therefore include human-factors testing, not just content accuracy.
5. The service fails safely under realistic disruption
Define safe behaviour for lost speech recognition, stale retrieval, model timeout, GPU saturation, network degradation and unavailable business APIs. Evidence should show bounded retries, reduced-service modes, human handover, preserved transaction integrity and recovery. The NCSC’s secure-deployment guidance recommends appropriate security evaluation before release and clear communication of known limitations and failure modes.
6. Human oversight can change the outcome
Do not satisfy this claim with “a human is available”. Specify what operators can see, the deadline for intervention, their authority and the deterministic controls they can use. Evidence should include rehearsals of pause, restrict, hand over and stop actions. Yepic’s guide to the operator control plane for AI avatars explains how to connect oversight roles to live controls.
7. The deployed release remains governed
Show that the organisation can identify what is running, detect unauthorised change, preserve proportionate evidence, patch components and re-evaluate material updates. Link the assurance case to the exact model, prompt, policy, knowledge, voice, renderer, container, driver and infrastructure configuration. Yepic’s guides to controlling AI configuration drift and building privacy-minimised AI audit trails address two parts of that evidence chain.
Use an evidence record, not an evidence folder
A directory full of test reports is not an assurance case. For each evidence item, record:
- the claim and release it supports;
- the test method, dataset, environment and date;
- the result, threshold and statistical uncertainty where relevant;
- the author, reviewer and degree of independence;
- the populations, languages, channels and failure conditions covered;
- known exclusions, conflicts and limitations;
- where the immutable artefact is stored and who may access it;
- its expiry or refresh rule; and
- the owner responsible for remediation if it stops supporting the claim.
Prefer evidence from the assembled service in an environment representative of production. Component tests still matter, but their argument should explain why they transfer. If the evaluation used a different model revision, GPU precision, browser, network path or knowledge corpus, record the difference rather than silently treating the result as equivalent.
NIST’s voluntary AI RMF Measure playbook asks organisations to document performance, assumptions, boundaries, limitations, deployment-context differences and ongoing monitoring. It also notes the value of independent perspectives when reviewing system-safety evidence. Independence should be proportionate: the reviewer needs sufficient competence, separation and authority to challenge the delivery team, even when a fully external audit is not required.
Record challenges and defeaters
An assurance case is strongest when it exposes what could make its argument fail. Add a challenge register beside the positive evidence. Typical entries include:
- evaluation data does not cover an important accent, dialect or accessibility need;
- a supplier report applies to a model version that is no longer deployed;
- the test environment did not reproduce production latency or concurrency;
- a guardrail was tested in English but the service also supports Arabic;
- the claimed human response time is incompatible with the staffing model;
- monitoring can detect an error but cannot stop the consequential action; or
- an evidence source is produced by the same team whose decision it validates.
For each challenge, state whether it is resolved, mitigated, accepted for a limited period or severe enough to defeat the claim. This prevents a green summary from concealing an expired test or a material coverage gap.
Make assurance continuous through change
Evidence has a shelf life. Define change triggers before production: model or prompt updates, a new knowledge source, policy-threshold changes, new languages, voice or avatar changes, browser releases, GPU or driver changes, new business actions, revised user groups, incident findings and material traffic shifts.
Not every change requires full re-assurance. Map each trigger to affected claims and a minimum evidence set. A caption-style change may need accessibility and rendering checks; a new action API may reopen identity, authorisation, failure safety and oversight claims. The decision record should show why unaffected claims remain valid.
Continuous monitoring does not mean retaining every conversation. Use aggregate measures, sampled review, event records, configuration fingerprints and privacy-preserving traces where they can support the claim. Escalate to more detailed evidence only under approved conditions.
Deployment model changes the evidence burden
Customer-hosted deployment can keep selected models, content and telemetry within the organisation’s environment and make internal configuration, identity and monitoring evidence directly accessible. It also places more operational evidence on the customer: GPU health, patch state, capacity, network paths, backups and configuration must all be governed.
Private or sovereign cloud can offer dedicated controls and jurisdictional choices while retaining more managed operations. Public cloud can simplify maintenance and provide mature platform evidence, but customers may have less control over underlying model or service changes. None of these architectures is inherently assured. The case must state which party controls each component, which evidence crosses the boundary and which assumptions depend on a supplier.
Yepic can scope cloud, private-cloud, sovereign and customer-hosted avatar systems, including deployment on customer-controlled GPUs where appropriate. The component boundary, evidence interface and responsibility split require custom implementation.
Take twelve questions to the production gate
- What exact use, release, environment and period does the top-level claim cover?
- Who has authority to accept residual risk, and when does that decision expire?
- Which seven claim domains apply, and why is any domain excluded?
- Does each claim have an argument, or merely an attached document?
- Was evidence collected from the assembled service under representative conditions?
- Which users, languages, channels and failure modes were not evaluated?
- Who reviewed the evidence, and could that reviewer challenge release?
- What open challenge could invalidate the conclusion?
- Can the team identify the exact runtime configuration the evidence covers?
- Which changes trigger partial or full re-assurance?
- What monitoring keeps each claim current without collecting unnecessary content?
- Can operators restrict or stop the service when evidence no longer supports a claim?
Apply the method to the integration, not just the avatar
Yepic’s Abu Dhabi Aviation and Oracle enterprise avatar integration joined enterprise data, APIs, an iframe, real-time streaming, captions, microphone behaviour, WebRTC and browser remediation across development and production environments, with cybersecurity support and ongoing maintenance. It is evidence that production avatar work spans many interdependent controls; it is not presented as a completed customer-hosted assurance-case implementation.
The transferable lesson is to make the integration itself the object of assurance. Start with the decision the organisation needs to make, write the bounded claim, decompose it across the whole service, connect every material assertion to current evidence and show what would force the decision to be revisited. That gives a CIO, risk committee or procurement team something stronger than a promise: a conclusion they can inspect, challenge and keep current.