AI Load Testing for Avatars: Measure the Whole Conversation
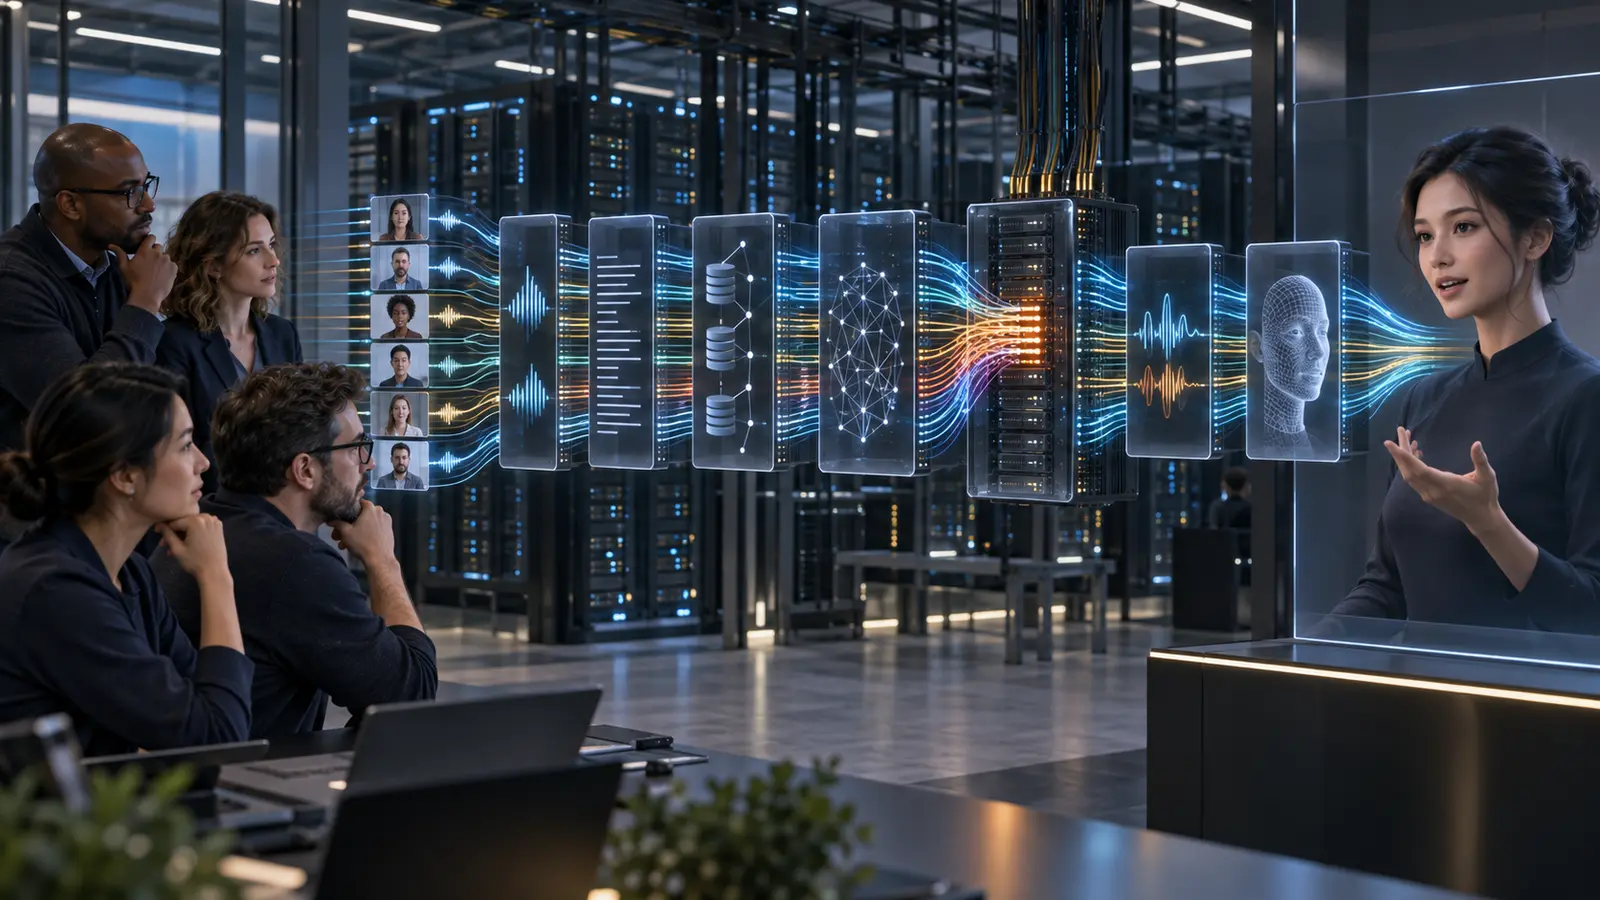
AI load testing for a real-time avatar should measure the whole conversation, not just the language model. A credible test sends representative audio through speech recognition, retrieval, reasoning, voice synthesis, avatar rendering and the media path while concurrency rises. It records both system performance and what the user experiences. The result is a defensible operating envelope: the traffic a specific build can serve, on specified infrastructure, while meeting agreed latency, quality and recovery thresholds.
That distinction matters for banks, governments and regulated enterprises. An LLM endpoint can look fast while users wait for speech to be recognised, a knowledge query queues, the first audible word arrives late or the video freezes. Conversely, a GPU may appear busy without the experience breaching its target. Load testing connects those layers before a pilot becomes a production service.
Define the workload before choosing a tool
A target such as “support 100 users” is incomplete. It does not say whether those users are silent, speaking simultaneously, asking short questions or running five-minute multilingual interviews. Start with a versioned workload contract that describes six dimensions.
- Arrival pattern: steady traffic, scheduled peaks, sudden bursts or a mixture. A transport hub at disruption time behaves differently from an appointment service.
- Session behaviour: duration, think time, turns per session, interruptions, abandoned sessions and reconnects.
- Language and content mix: audio length, accents, transcription difficulty, retrieval volume, prompt size and response length. Arabic–English switching may exercise a different path from monolingual English.
- Channel profile: managed kiosk, office browser, mobile device or contact-centre desktop, including expected bandwidth, jitter, packet loss and use of TURN relays.
- Dependency mix: knowledge searches, identity checks, business APIs, captions, translation, human handover and actions that require confirmation.
- Priority classes: anonymous information, authenticated service, accessibility session and operator-supervised interaction may have different admission and performance rules.
Use measured or carefully anonymised production distributions where lawful and available. If the service is new, build hypotheses from the intended journey and label them as assumptions. A neat test made entirely of identical prompts at fixed intervals is useful for a baseline, but it is not a production forecast.
Modern inference tools illustrate the principle. NVIDIA’s September 2026 AIPerf guidance supports constant, Poisson and bursty arrival patterns, variable input and output lengths, trace replay and percentile reporting. Those capabilities are useful examples, not requirements for a Yepic deployment. Whatever tool is selected, confirm that the load generator itself does not become the bottleneck.
Measure the seven-stage conversation path
Time to first token is only one component of perceived responsiveness. Instrument a correlation identifier across the complete turn:
- Capture and turn detection: microphone permission, audio buffering, voice activity detection and end-of-turn decision.
- Speech processing: speech recognition and, where required, language identification or translation.
- Grounding and actions: authorisation checks, knowledge retrieval, reranking and calls to enterprise systems.
- Reasoning: queue time, time to first token, generation rate and full model response.
- Voice: text-to-speech queue time, time to first audio and continuity of streamed speech.
- Avatar rendering: animation preparation, frame generation, encoding, frame rate and audio–visual synchronisation.
- Delivery: signalling, relay selection, network transit, jitter buffering, decoding and first playable media at the device.
The most useful top-line measure is often time to first meaningful audiovisual response: from the user finishing a turn to hearing and seeing a coherent reply. Keep the component timings underneath it. Without both views, teams can see that a session is slow but cannot locate the queue.
For browser delivery, the W3C WebRTC statistics model defines measurements exposed through getStats(). Relevant signals include round-trip time, jitter, packets lost, frames decoded or dropped, frame rate, freeze count and jitter-buffer delay. The specification is a Candidate Recommendation Draft, so implementations and privacy constraints still need validation in the target browsers.
Use four tests, not one headline number
1. Baseline test
Run one representative session on an otherwise quiet environment. This establishes the minimum practical latency for the build and confirms that instrumentation is aligned. Repeat it for each important language, voice, avatar and client class. A baseline is a comparison point, not evidence of capacity.
2. Ramp test
Increase arrival rate or concurrent active turns in controlled steps. At each step, hold long enough to observe stable queues. The goal is to find the capacity knee: the point where a small increase in load causes a disproportionate increase in tail latency, errors or quality loss. Set the planned operating limit below that point with headroom for failover, maintenance and uneven traffic.
3. Burst-and-recovery test
Apply a short, plausible spike: a flight disruption, a benefits deadline or the end of a keynote. Observe admission controls, queue growth, session continuity and the time needed to return to normal. This complements rate limiting for real-time avatar capacity: the policy protects the system, while the test verifies what happens when that policy activates.
4. Soak test
Run a realistic mix for hours, not minutes. Look for GPU-memory fragmentation, unreleased media sessions, growing queues, cache drift, expiring credentials and gradual audio–video degradation. Include reconnects and ordinary component rotation. Many production failures are cumulative rather than dramatic.
Fault injection remains a separate discipline. A load test asks how the healthy system behaves under demand; AI resilience testing deliberately removes or degrades dependencies. Mature programmes combine them, but they should not confuse their evidence.
Record performance and conversational quality together
A test can pass technically while failing for the person in front of the avatar. Track the distribution, not just the mean, and group results by journey, language and channel.
- Responsiveness: p50, p95 and p99 turn latency; time to first token, first audio and first rendered frame; queue wait and cold-start time.
- Throughput: admitted sessions, active turns, completed turns, tokens and audio seconds per unit of time.
- Reliability: rejected, timed-out, interrupted and retried operations; failed dependencies; incomplete or abandoned sessions.
- Compute: GPU utilisation and memory, CPU, host memory, encoder load, storage and network saturation.
- Media quality: delivered frame rate, frozen or dropped frames, audio gaps, jitter, packet loss, relay use and synchronisation.
- Conversation quality: transcription accuracy on a controlled corpus, grounded-answer checks, correct language and voice, interruption behaviour, caption timing and successful action completion.
Do not optimise one number in isolation. Batching may increase throughput while delaying the first response. Shorter answers may reduce latency while omitting necessary information. Lower rendering quality may preserve continuity on constrained networks. Each trade-off needs an explicit user and risk decision.
The acceptance thresholds should flow from the intended service and its end-to-end avatar service objectives. There is no universal acceptable p95, concurrency figure or GPU utilisation percentage. A public information kiosk, an authenticated banking journey and an emergency transport service do not have the same consequences of delay.
Make every run reproducible
A load-test result without its context is not portable evidence. Preserve a test record containing:
- workload version, data source and permitted use;
- application, model, policy, voice and avatar build identifiers;
- GPU, CPU, memory, driver, runtime and orchestration configuration;
- autoscaling, batching, cache and admission settings;
- client location, browser, codec, network impairment and relay path;
- warm-up method, run duration, repetitions and load-generator capacity;
- raw percentile results, quality checks, failures and operator observations;
- the accepted operating envelope, headroom, exceptions and approver.
This record connects performance engineering to GPU capacity planning for real-time avatars. Sizing proposes the configuration; load testing validates a particular configuration and build. Repeat the critical suite after model, runtime, driver, rendering, network or policy changes rather than assuming yesterday’s result still applies.
Cloud and on-premise tests answer different questions
Public cloud can make it easier to generate temporary load, add regions and compare instance types. A managed service may also hide component telemetry or apply provider-side quotas. Private cloud and sovereign cloud can offer more control over location and network paths, but the control boundary must still be documented.
Customer-hosted inference lets the enterprise test its own GPUs, cluster, security controls and network. It also makes the customer responsible for providing enough test capacity, separating the load generator from the system under test, monitoring thermal and power limits, and preserving representative non-production data. On-premise is not automatically faster, cheaper or easier to validate.
Yepic can support cloud, private-cloud and customer-hosted avatar architectures through properly scoped implementations. The relevant proof is not a generic benchmark. It is a test on the intended architecture, using the intended models, languages, browsers and enterprise dependencies.
Twelve questions for the production gate
- Does the workload represent arrivals, turn overlap and session duration rather than only user count?
- Are the busiest languages, channels and dependency paths included?
- Can one trace link capture to first playable audio and video?
- Are p95 and p99 results visible for every important stage?
- Has the load generator been shown not to limit the result?
- Where is the capacity knee, and how much usable headroom remains?
- What happens to admitted and waiting users during a burst?
- Does conversational or media quality degrade before technical failure?
- Can the service recover without orphaned sessions or a growing queue?
- Has a long soak exposed memory, credential or media-session leakage?
- Is the run reproducible from its workload and runtime records?
- Which changes require the test suite to run again?
Turn an integration test into production evidence
The Abu Dhabi Aviation and Oracle avatar integration shows why the test boundary must be wider than the model. That project involved development and production environments, API and iframe integration, real-time streaming, captions, microphone behaviour, WebRTC and network testing, browser remediation, cybersecurity support and ongoing maintenance. It is evidence of enterprise integration breadth, not a claim of a completed customer-hosted load-testing programme.
For a new service, begin with one representative, replayable journey. Instrument the complete turn, run the four test classes and publish the resulting operating envelope to architecture, operations, risk and procurement. That gives decision-makers something more useful than a demo: evidence of how this exact avatar system behaves when real conversations compete for finite resources.