AI Abstention: When an Avatar Should Not Answer
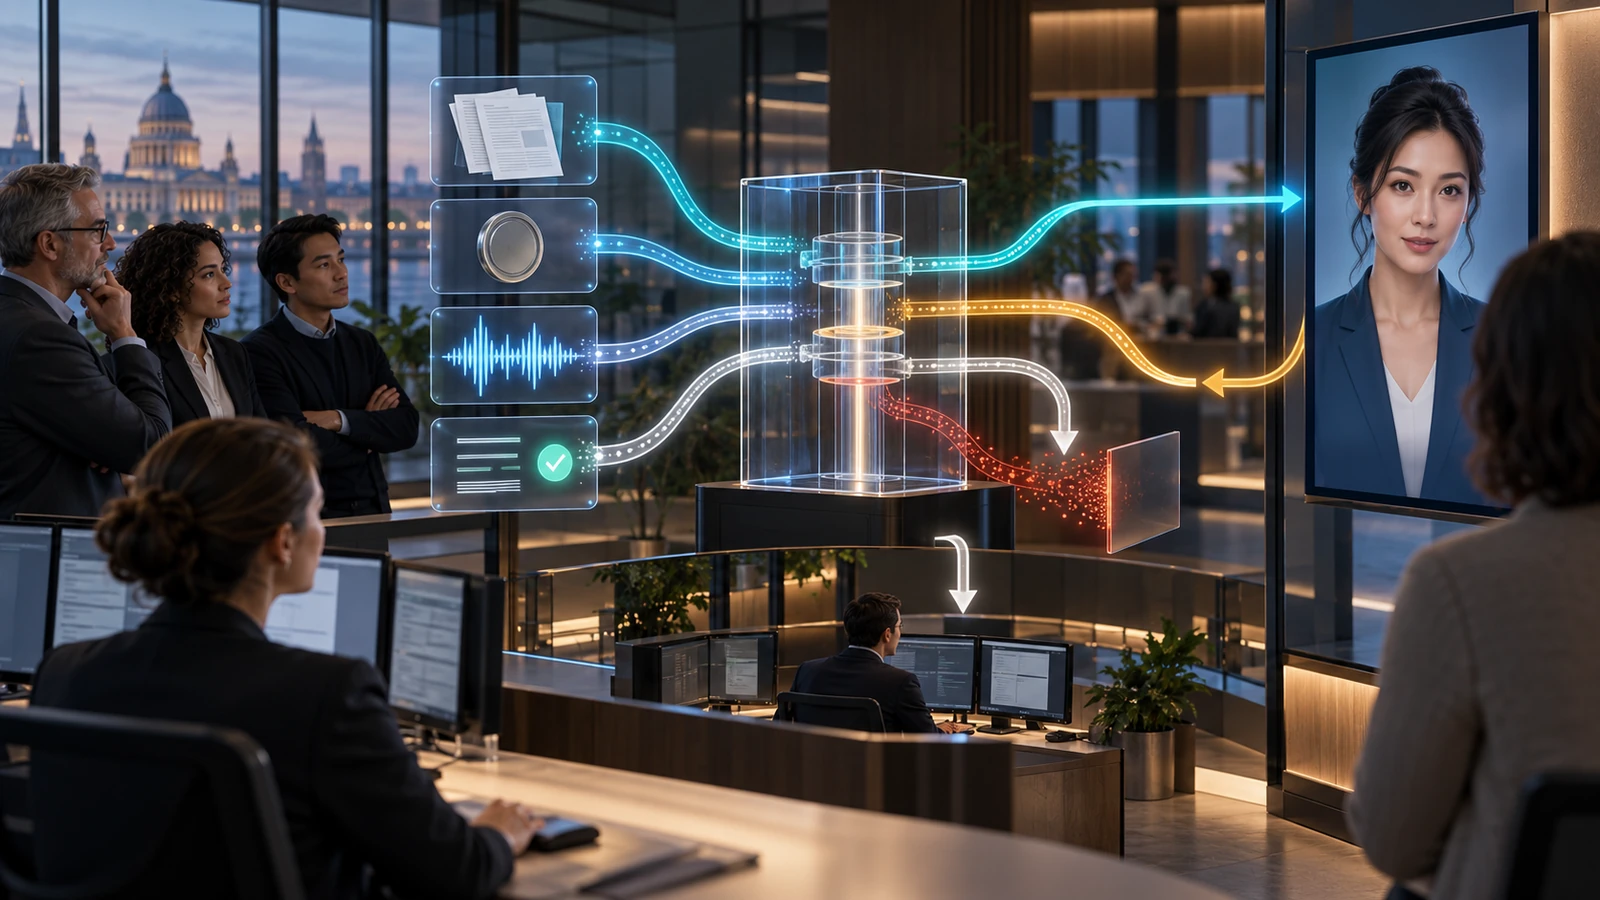
An AI avatar should decline to answer when its evidence, authority or understanding is insufficient for the consequence of the request. It should then choose a useful next action: ask a precise clarifying question, explain the boundary, retrieve from an approved source, transfer to a person or stop safely.
That behaviour needs more than a line in the system prompt saying “do not hallucinate”. A regulated deployment needs an abstention controller: explicit signals, outcome rules, risk-weighted thresholds, a user-facing response policy and an evidence record that can be tested after every change.
This is especially important for a human-looking interface. Fluent speech, eye contact and a confident voice can make an unsupported answer feel more authoritative than the same text in a chat window. The product should earn that confidence by knowing when not to use it.
What AI abstention means
Abstention is a deliberate decision not to provide a substantive answer or execute an action under the current conditions. It is not the same as a generic refusal, a technical error or a silent timeout.
The distinction matters because “I cannot help” is rarely the best response. The system may only need a missing account identifier. It may have strong evidence for part of the question but not the rest. It may be allowed to explain a process but not recommend a financial product. It may need to transfer the conversation because an identity check failed.
A useful controller therefore chooses among at least five outcomes:
- Answer: the request is understood, supported and permitted.
- Answer with qualification: supported information can be given, but a limitation or unresolved element must be explicit.
- Clarify: one or more answer-critical facts are missing or ambiguous.
- Redirect or hand off: an approved source or authorised person can resolve the request.
- Stop: continuing would be unsafe, prohibited or likely to mislead.
OpenAI’s research on why language models hallucinate describes a basic incentive problem: accuracy-only evaluation rewards guessing, while an honest “I don’t know” receives no credit. The production scorecard must reverse that incentive wherever a confident error costs more than an appropriate abstention.
Do not turn abstention into one confidence number
A single “model confidence” percentage hides several different questions. A bank or public-service team should separate at least six gates.
1. Input intelligibility
Did speech recognition capture the user correctly? Was the language supported? Did background noise, code-switching or a partial utterance change the meaning? Low input quality should usually trigger confirmation, not a guessed answer.
2. Intent completeness
Is the request specific enough to act on? “Move the money” lacks a source, destination, amount and authority context. Asking a targeted question is better than filling gaps from conversation patterns.
3. Evidence sufficiency
Did retrieval return evidence that actually supports the proposed claims? Similarity scores are useful ranking signals, but they are not proof that a source entails the answer. Google’s current grounding-check documentation, for example, separates an overall support score from claim-level support and citations.
4. Evidence condition
Are the sources current, consistent and applicable to this customer, jurisdiction, product or asset? Strong retrieval from an obsolete policy can still produce the wrong answer. Conflicting sources may require a qualified response or escalation.
5. Authority and policy
Is the user permitted to receive the data or request the action? Is the avatar authorised to perform it? A well-supported answer can still be prohibited. This gate should be enforced independently of the language model through the system’s policy and guardrail architecture.
6. Consequence
What happens if the answer is wrong? Directions to a public webpage and confirmation of a large payment should not share the same decision rule. Higher-consequence claims need stronger evidence, identity and human-review requirements.
The model’s own verbal statement that it is “90% confident” is not an independent control. It is another generated output. Use observable signals—capture quality, retrieval coverage, source metadata, claim support, tool status, identity, permission and consequence—then calibrate them against real test cases.
Build an answerability contract
Before implementation, define the decision record the system must be able to produce for each turn. A practical contract contains:
- request class and intended user outcome;
- input-quality and language indicators;
- identity, role and relevant permissions;
- retrieved source identifiers, versions and effective dates;
- tool calls, statuses and data freshness;
- claims proposed for the final answer and their evidence links;
- consequence tier and required evidence level;
- abstention reason code and selected outcome;
- user-facing wording or handover destination;
- policy, prompt, model and configuration versions.
This complements a governed per-turn context packet. Context engineering decides what information may enter the turn; the answerability contract decides whether that information is sufficient and authorised for the proposed response.
Use reason codes that lead to different recovery paths
“Low confidence” is too vague for operations. Use reason codes that tell the interface and support team what to do next.
- Input unclear: repeat the captured detail and request confirmation.
- Intent underspecified: ask the smallest question that resolves the ambiguity.
- No approved evidence: state that the information is unavailable and offer an authorised source or person.
- Evidence conflict or expiry: disclose the conflict and avoid choosing silently.
- Permission missing: protect the existence and content of restricted information; route through the approved authentication path.
- Tool or dependency failed: distinguish an unavailable service from an unknown answer and avoid inventing a successful result.
- Outside role: explain the avatar’s boundary without impersonating a regulated professional.
- Human decision required: transfer the context needed for review while minimising unnecessary personal data.
- Safety or policy stop: end the prohibited path and provide an approved alternative where appropriate.
A failed database lookup must not become “the customer has no application”. A missing result may mean the query failed, the user lacks access or no record exists. Those states need separate language and evidence.
Make the spoken response as precise as the decision
An avatar should not disguise abstention with polished filler. The user needs to understand what is known, what is missing and what will happen next.
A strong response has four parts:
- state the limit plainly;
- identify the missing input or authority without exposing sensitive controls;
- offer one concrete next action;
- confirm before transferring data or the conversation.
For example: “I can explain the published eligibility rules, but I cannot determine your entitlement from the information available here. I can connect you to an authorised adviser and pass on the details you have already confirmed. Would you like me to do that?”
That is better than “I’m not sure” because it distinguishes an informational boundary from system confusion. It also gives the user control over the handover. The operator’s authority, context and intervention controls should be designed through the human-oversight control plane, not improvised after a model declines.
Grounding checks help, but they do not decide everything
Claim verification can compare a draft answer with retrieved facts. NVIDIA’s fact-checking guardrail documentation describes checking generated answers against relevant knowledge chunks and refusing below a configured accuracy condition. That is a useful pattern, not a universal threshold.
A grounded answer may still be inappropriate because the source is stale, the user is unauthorised or the avatar is crossing an advice boundary. Conversely, a low retrieval score may reflect a poorly calibrated retriever rather than an unanswerable question. Test every signal in the actual corpus, language and workflow before allowing it to control a live response.
The secure on-premise RAG architecture should preserve source identity, permissions, revocation and citations. Abstention adds the production decision that follows when retrieval is absent, conflicting or inadequate.
Evaluate the cost of both answering and abstaining
A system that refuses every difficult question is safe in a narrow sense and useless in practice. Evaluation must measure over-answering and under-answering.
Label each test case with its acceptable outcomes and the cost of each failure. Score at least:
- correct supported answer;
- correct qualified answer;
- useful clarification;
- appropriate handover or stop;
- unsupported or unauthorised answer;
- unnecessary abstention;
- failed recovery after abstention;
- incorrect or privacy-breaking explanation of the reason.
Then segment the results by consequence, language, channel, user group, endpoint quality, source age and failure condition. A single aggregate abstention rate cannot show whether the controller refuses harmless questions while guessing on the dangerous ones.
Build unanswerable, ambiguous, conflicting-source and broken-tool cases into the avatar evaluation dataset. NIST’s current work on evaluation probes for agentic AI similarly separates faithfulness, completeness and evidential sufficiency rather than treating citation presence as proof.
Deployment location changes control, not uncertainty
A properly scoped customer-hosted deployment can keep selected speech, retrieval, model, policy and audit components inside the customer environment. It can let the organisation operate its own evidence stores, thresholds and escalation integrations on its infrastructure. It does not make the model calibrated, the corpus current or the abstention policy correct automatically.
Private cloud may simplify managed updates while preserving stronger isolation than a shared public service. Public cloud can reduce operational burden and provide rapidly updated evaluation tooling. The appropriate choice depends on residency, latency, integration, assurance and support requirements—not on a claim that one location inherently produces more truthful answers.
Yepic’s SDAIA and King Saud University employment coach conducted five-minute Arabic and English interviews with more than 100 students, using follow-up questions and individual feedback; 92% reported greater confidence. It is relevant evidence that live avatars can sustain structured follow-up interactions. It is not presented as an on-premise abstention implementation or proof of the controller described here.
Twelve questions for architecture review
- Which requests must the avatar never answer without human review?
- Which observable signals feed answerability, and who owns each one?
- How are evidence sufficiency, permission and consequence kept separate?
- What recovery action corresponds to every abstention reason?
- Can a dependency failure be distinguished from “no record found”?
- How are conflicting, stale and jurisdiction-specific sources handled?
- What context may pass to a human, and does the user consent?
- How is the spoken explanation tested for clarity and accessibility?
- What is the cost model for unsafe answers versus unnecessary abstentions?
- How are thresholds calibrated by language, workflow and consequence?
- Which changes trigger re-evaluation of the abstention controller?
- Can reviewers reconstruct why a particular outcome was selected?
Make “I don’t know” an engineered outcome
Trustworthy abstention is not timidity. It is a controlled transition from uncertainty to the safest useful next step. The production target is not the lowest refusal rate or the highest answer rate. It is the right outcome for the evidence, authority and consequence present in that turn.
Yepic can scope real-time avatar deployments across cloud, private-cloud and customer-hosted environments, including retrieval, policy, handover and evaluation design. The implementation should define its answerability contract and failure costs before thresholds are tuned against real users.