AI Model Quantisation: Validate the Whole Avatar Stack
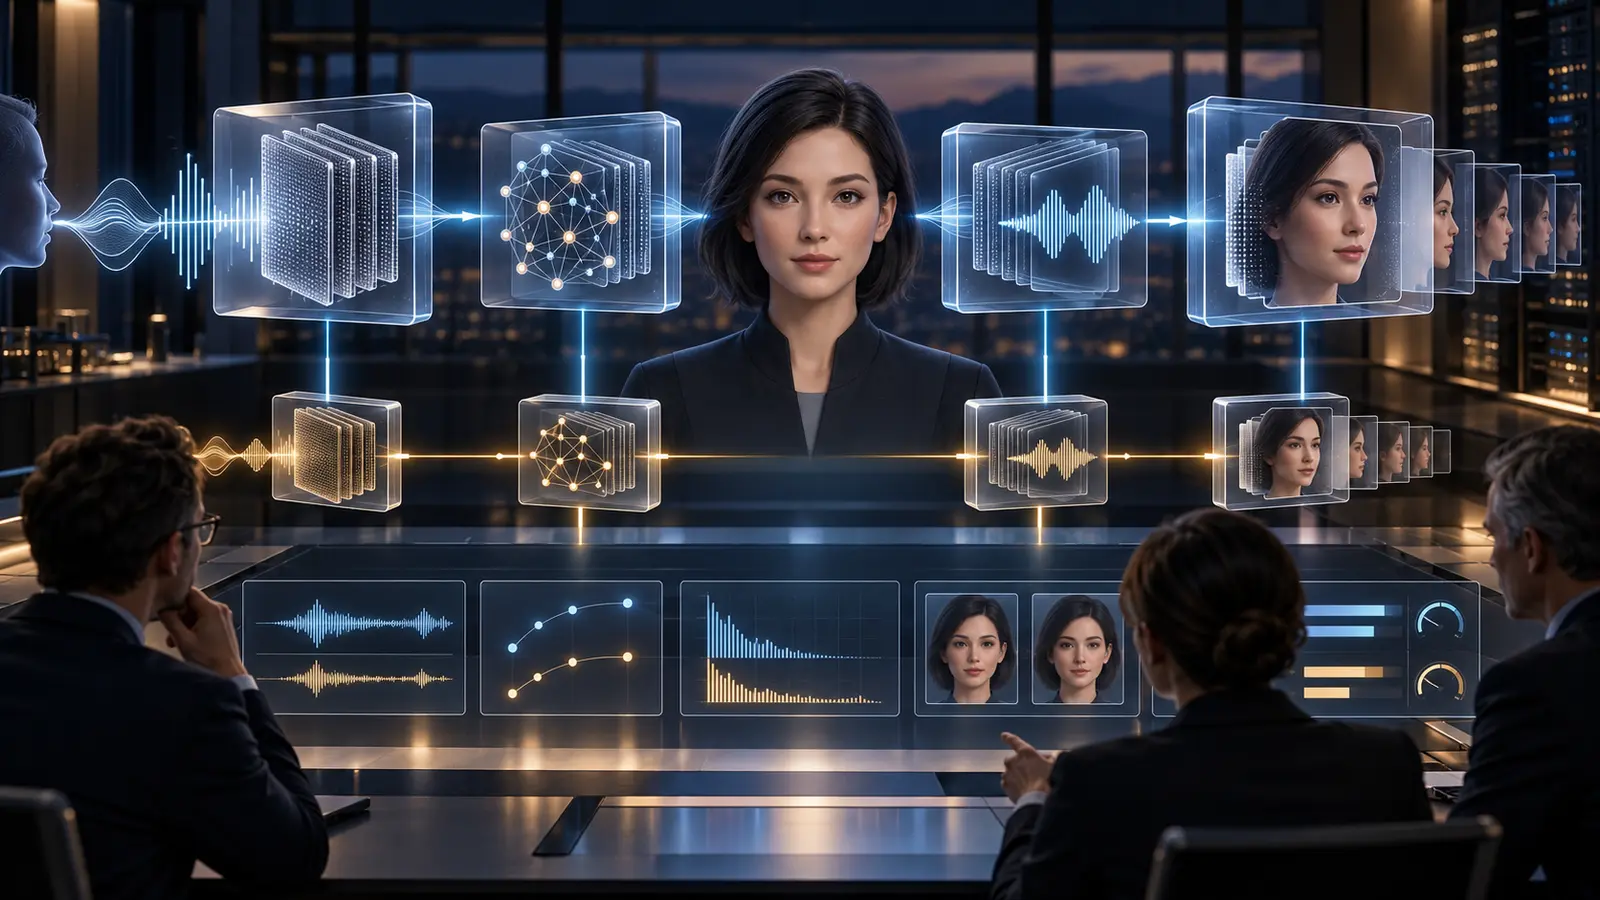
AI model quantisation should be approved as a measured system change, not treated as a free reduction in GPU memory. Lower precision can make a model smaller and may improve throughput or latency, but the result depends on the model, the quantisation scheme, the runtime kernels and the target hardware. It can also change recognition, reasoning, tool selection, pronunciation or rendering quality in ways that a generic benchmark will not reveal.
For a real-time AI avatar, the practical rule is simple: quantise one component at a time, compare it with an unchanged baseline on the customer’s actual workload, and release it only when the whole conversation still meets its quality, safety and performance thresholds.
What model quantisation changes
Neural-network weights and intermediate calculations are normally represented using numerical formats with a defined precision. Quantisation maps some of those values to a lower-precision format. Depending on the method, it may change weights, activations, the key-value cache used by a language model, or a combination of them.
The attraction is straightforward. Lower-precision values can require less memory and memory bandwidth. Supported hardware may also execute the relevant operations more efficiently. That can allow a model to fit on a smaller GPU, leave more memory for concurrent sessions or reduce the number of devices required by a service.
But “fewer bits” is not a performance specification. ONNX Runtime’s quantisation documentation explicitly notes that the transformation is not lossless and may affect accuracy. It also explains that older hardware can deliver no gain—or worse performance—when it lacks suitable instructions and must pay additional quantise/dequantise overhead.
Do not quantise “the avatar” as one object
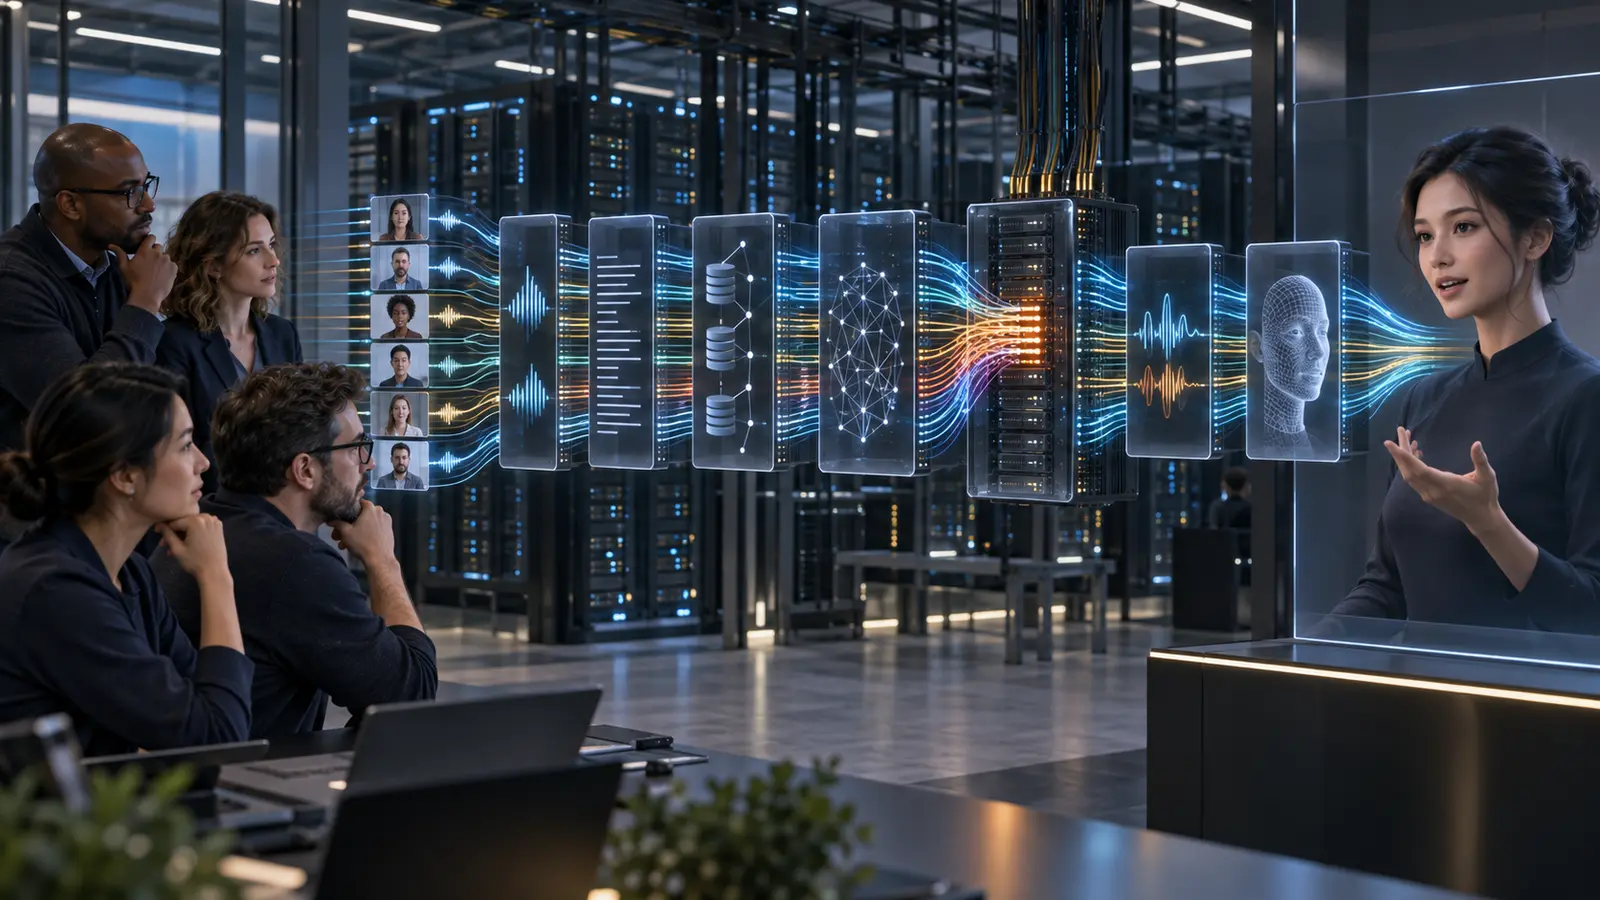
A live avatar is a pipeline of different models and deterministic services. Each component has a different numerical profile, failure mode and acceptance test.
- Speech recognition: test names, account references, technical vocabulary, dialects, code-switching, background noise and partial speech. A lower average word-error rate can still conceal damaging entity errors.
- Retrieval and reasoning: test grounded answers, long context, refusal, citations, multi-turn consistency and correct tool selection. A plausible sentence is not proof that the right evidence or permission boundary was used.
- Policy and classification: measure false acceptance and false refusal for high-risk intents. Small score changes can have asymmetric business consequences.
- Text-to-speech: test intelligibility, pronunciation, language switching, voice identity, prosody and time to first audio. A compact voice model may be fast but mishandle regulated terminology or personal names.
- Avatar rendering: inspect lip synchronisation, expression, motion stability, frame rate and artefacts across identities, camera angles and response lengths.
- Perception models: evaluate the intended signals across relevant users and environments. Do not infer that a quantised vision or audio model preserves performance for every population.
This stage-by-stage view prevents a common mistake: replacing several models at once, seeing an end-to-end regression and having no reliable way to locate it.
Choose among four implementation paths
1. Weight-only post-training quantisation
Only stored model weights move to a lower precision while activations remain at a higher precision. This can reduce the resident model footprint and may suit hardware that cannot accelerate every lower-precision activation format. It is often a useful first experiment, but runtime support still matters.
2. Static post-training quantisation
Weights and selected activations are quantised using parameters calculated in advance from calibration data. The quality of that calibration set matters. Audio, language, visual identities and conversation lengths should reflect the proposed service—not a convenient generic sample.
3. Dynamic quantisation
Activation parameters are calculated during inference. This can preserve accuracy better in some cases, but introduces computation at runtime. “Dynamic” therefore does not automatically mean faster. The candidate needs to be measured on the deployed runtime and workload.
4. Quantisation-aware training
The model is trained or fine-tuned while simulating lower-precision behaviour, allowing it to adapt. It can recover quality when post-training methods miss the acceptance threshold, but adds training data, compute, lineage and validation obligations. It may also be unavailable when the organisation cannot retrain the model or lacks the necessary rights.
Official vLLM documentation illustrates why the choice cannot be separated from infrastructure. Its current quantisation compatibility matrix shows that implementations vary across GPU generations, other accelerators and CPUs. The related LLM Compressor guidance recommends selecting a scheme according to both hardware and deployment requirements.
Create a precision decision record
For every candidate, keep one record that architecture, risk and operations teams can review. It should include:
- component, model identity and full-precision baseline version;
- quantisation method, numerical format and which tensors are affected;
- toolchain, runtime, drivers, kernels and build configuration;
- target GPU or CPU architecture and required hardware capabilities;
- calibration dataset identity, provenance and coverage, where used;
- licence and modification rights for the derived artefact;
- quality, safety and performance acceptance thresholds;
- benchmark workload, concurrency and test environment;
- observed regressions, excluded layers and known limitations;
- release owner, approval, rollback artefact and review trigger.
This record also prevents “INT8” or “FP8” becoming an ambiguous label. Weight-only INT8, weight-and-activation INT8 and a mixed-precision graph are different deployments. Even two artefacts described with the same headline format may use different group sizes, scaling, calibration or kernels.
Use a seven-step qualification process
- Freeze the baseline. Record the existing model, runtime, prompts, knowledge, policies, hardware and complete workload.
- Define the reason. State whether the goal is model fit, concurrency, latency, power, cost or deployment on a particular accelerator.
- Check compatibility. Confirm that the target hardware, driver, runtime and operator set accelerate the proposed format. Loading successfully is not the same as receiving a speed benefit.
- Quantise one component. Keep the rest of the pipeline unchanged so that quality and performance movement can be attributed.
- Run component tests. Use domain, language, safety and edge cases appropriate to that stage.
- Run whole-conversation tests. Measure interaction quality, tail latency, frame delivery, audio-video synchronisation and successful completion under representative demand.
- Release with rollback. Retain the baseline, use a staged rollout and define which signal automatically stops or reverses the change.
Yesterday’s guide to building an avatar evaluation dataset describes the versioned interaction cases needed for this comparison. Quantisation is precisely the kind of change for which a stable golden set, separate challenge set and production-derived sample are useful.
Measure memory, speed and completed conversations
A useful benchmark report should include peak resident GPU memory, model load time, time to first response, per-stage P50 and tail latency, sustained throughput, queue depth, error rate and the number of simultaneous conversations that remain within the agreed experience limits.
Measure the complete service as well as the individual model. A smaller language model footprint may create room for more sessions but still increase end-to-end latency if the selected kernel is inefficient. Faster text generation may have no user-visible benefit if speech synthesis or video encoding remains the bottleneck.
Do not report infrastructure improvements without outcome measures. Count conversations that complete with the required permission, accuracy, safety, voice and visual quality. A release that supports more sessions while increasing incorrect tool calls is not an efficiency improvement.
Use end-to-end AI load testing to find the capacity knee rather than extrapolating from one warm request. Yepic’s GPU sizing framework also explains why model residency, concurrency, failure reserve and service thresholds belong in the same capacity decision.
Protect the calibration and evaluation boundary
Static quantisation may use calibration examples to determine suitable ranges for activations. Those examples are operational data assets. Record where they came from, which personal or confidential information they contain, who may access them and how long they are retained.
The calibration set and evaluation set should not be casually collapsed into one dataset. Calibration helps create the candidate artefact; evaluation tests whether that candidate generalises to the service. Keeping a held-out set makes the comparison more credible and reduces the risk of tuning directly to every release case.
For multilingual avatars, calibration and evaluation should include the relevant languages, dialects, code-switching patterns, names and audio conditions. A scheme that passes English text benchmarks may still alter an Arabic speech model, pronunciation system or mixed-language retrieval path.
Check whether the licence permits the derived model
Technical access to model weights does not establish every right needed to modify, optimise, store, distribute or support a quantised derivative. The answer depends on the applicable model licence, associated assets and deployment arrangement. Record the source artefact, licence version, permitted modifications, distribution conditions and supplier obligations before the optimised model enters a customer environment.
Yepic’s AI model-licensing rights matrix provides a broader method for reviewing models, voices, avatars, datasets, codecs and runtimes in a customer-hosted stack. This is an engineering and procurement control, not legal advice.
Cloud and customer-hosted trade-offs
A managed cloud provider may already select optimised precision, kernels and hardware behind an API. That reduces operational work, although the customer may have limited visibility into the exact artefact or when it changes. The buyer still needs outcome tests, region and data-handling controls.
Private-cloud or on-premise deployment gives the customer direct influence over the model artefact, runtime, GPU generation and release timing. It can make optimisation economically important because memory headroom and concurrency translate directly into owned capacity. It also transfers more validation, patching, rollback and evidence responsibility to the operating parties.
On-premise is not automatically faster. Quantisation is not automatically accurate. A four-bit label is not proof that a model will fit the target service. The deployment should be selected according to data boundary, utilisation, operational capability and verified performance.
Twelve questions for procurement and architecture review
- Which avatar components are quantised, and which remain at the baseline precision?
- Are weights, activations, cache or all three affected?
- Which exact hardware and runtime accelerate the proposed format?
- What calibration data was used, and does it represent the service?
- Which quality measures are reported separately by language and task?
- How are entity recognition, tool arguments, refusals and permissions tested?
- What are the memory, latency and throughput results under representative concurrency?
- Does the benchmark include speech, voice, rendering and network delivery?
- Which layers or operations remain at higher precision, and why?
- Do the model licence and supplier contract permit the optimised derivative?
- Can operations identify the precision artefact in every production session?
- What threshold triggers rollback to the full-precision baseline?
Where Yepic’s experience applies
Yepic has spent years developing proprietary talking-photo and real-time avatar technology, including work to optimise real-time inference for commercial GPUs. Private, sovereign and customer-hosted implementations can be scoped for a customer’s own environment and GPUs, alongside cloud or private-cloud options where those are more appropriate.
Yepic’s five-metre real-time agent at GAIN Saudi Arabia targeted a response time below one second and operated across three summit days alongside the holographic Farrah. The GAIN case study demonstrates live, low-latency avatar engineering. It is not evidence that the project used a particular quantisation scheme or was a customer-hosted deployment.
The sensible next step is a precision feasibility test: select one bottleneck component, freeze the baseline, build a representative calibration and evaluation pack, produce one hardware-compatible candidate and compare the complete conversation under load. That turns “can we run it in fewer bits?” into the question regulated buyers actually need answered: “does the optimised service still do the right thing?”